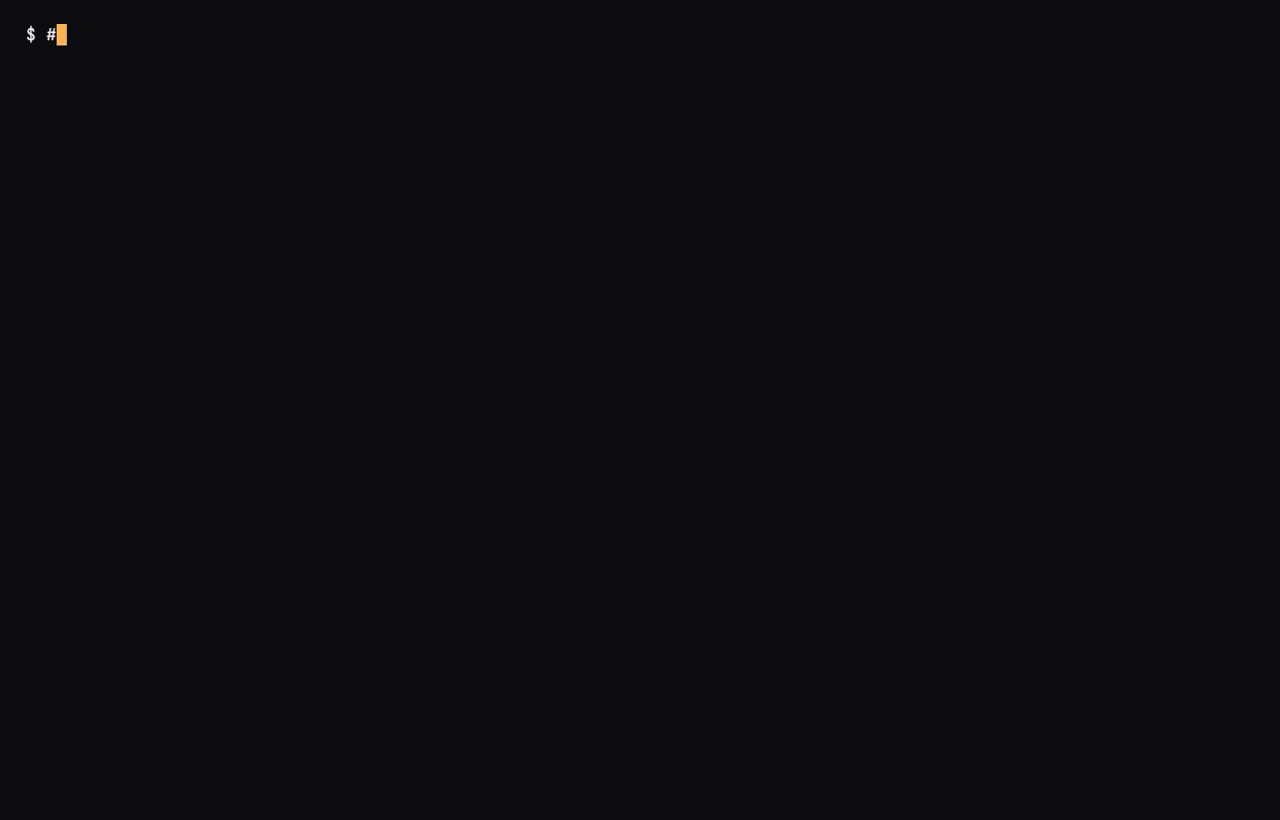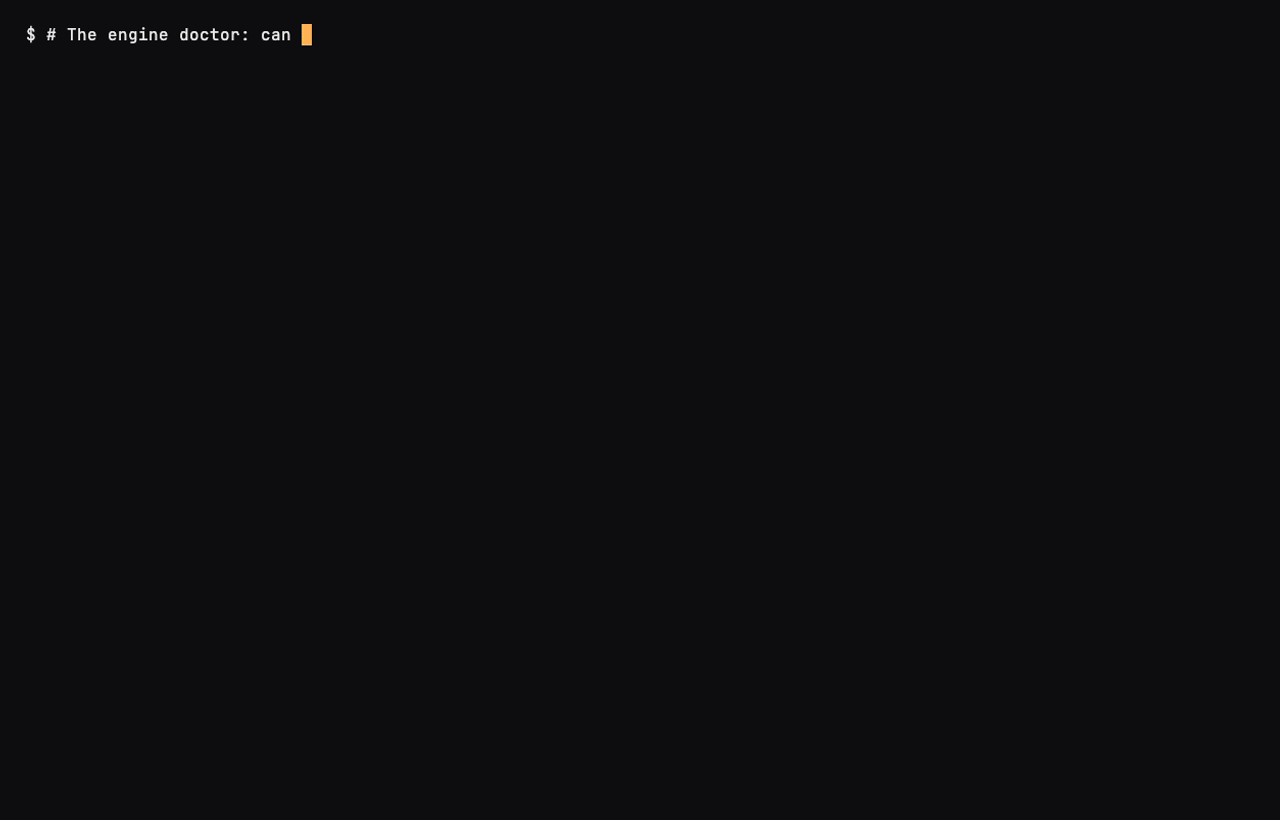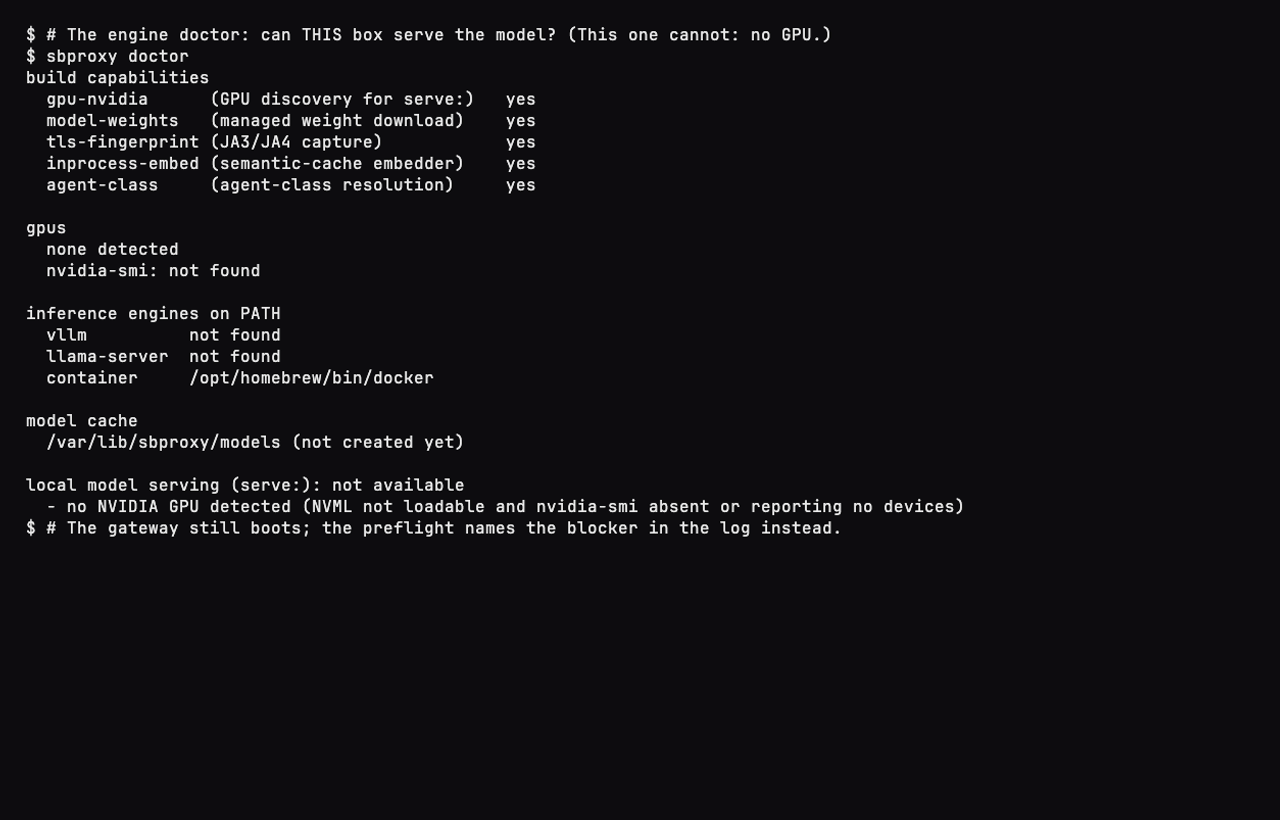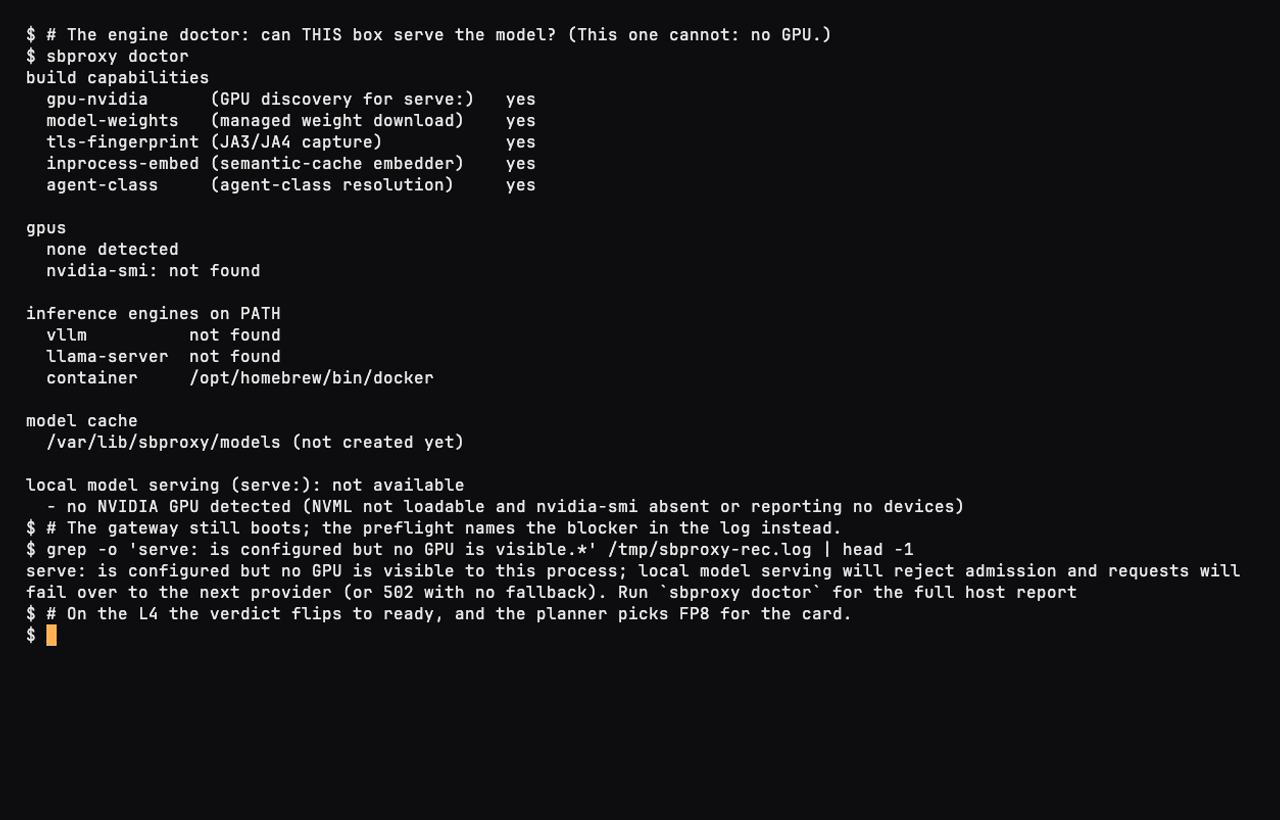
The recording shows the CPU half of this story: the preflight commands refusing a box with no GPU, which is exactly what they should do. The first-token half needs the L4 itself.
You have GCP credits and a model you want to run on your own terms. The open-weight releases from Qwen, GLM, and Gemma are good enough for real work now, but most serving guides stop at a bare vllm serve with nothing in front of it and no plan for the day you need a hosted fallback. SBproxy is built for exactly this gap: "Take control of your AI traffic." One Apache-2.0 binary routes to 72 providers or serves the weights on your own GPUs, and this page walks the serving half, from gcloud compute instances create to a first completion on a single NVIDIA L4.
A status note before you spend money. The model host is the newest part of SBproxy and is landing in phases. The released binary ships GPU discovery and managed weight download as default features, and the L4 in this guide is the reference card the whole path is certified against, by hand, at feature-complete points rather than by CI on every push. On a host with no GPU or no engine, a serve: block validates but starts no engine. Trust sbproxy doctor on your box over any document, including this one; model-host.md in the repo docs keeps the current status.
What you will build
A g2-standard-8 VM with one 24 GB L4, running an OpenAI-compatible gateway on port 8080. You name qwen3-14b in a serve: block. SBproxy resolves it through the built-in catalog to the Qwen/Qwen3-14B weights, fits a quant to the card (FP8, because an Ada-generation L4 has FP8 kernels), launches vLLM as a supervised subprocess on a loopback port, and routes chat completions to it. The same routing, guardrail, budget, and ledger planes that govern hosted providers apply to this local one, so the config you write here can grow a cloud spill lane later without rework.
Prerequisites
- A GCP project with
gcloudauthenticated (gcloud auth login) and L4 quota (NVIDIA_L4_GPUS) in your target region. Check before you create anything:gcloud compute regions describe us-central1 \ --format="value(quotas)" | tr ',' '\n' | grep -i l4 - A cost expectation. L4 boxes bill while they exist: the smaller
g2-standard-4runs about $0.71/hr on demand, roughly $516 a month if you forget it. The delete command is at the end of this page. Use it. curlfor sending requests, andjqif you like pretty JSON.- Optional: a Hugging Face token. The Qwen weights in this walkthrough are ungated, but Gemma and Llama sit behind click-through licenses, and a gated repo needs
hf_tokenin a model manifest (more on that below).
Install
Create the VM. The Deep Learning image ships the CUDA driver preinstalled, so there is no driver dance on first boot:
gcloud compute instances create sbproxy-l4 \
  --zone=us-central1-a \
  --machine-type=g2-standard-8 \
  --accelerator=type=nvidia-l4,count=1 \
  --maintenance-policy=TERMINATE \
  --image-family=common-cu124-ubuntu-2204 \
  --image-project=deeplearning-platform-release \
  --boot-disk-size=200GB \
  --boot-disk-type=pd-ssd \
  --metadata=install-nvidia-driver=True

gcloud compute ssh sbproxy-l4 --zone=us-central1-a
The repo wraps these commands in scripts/provision-l4.sh (up, ssh, down) if you would rather not retype them, and deploy/terraform/l4-demo is the Terraform version with a public IP, Let's Encrypt TLS, and a bearer token in front, for when this stops being an experiment.
On the box, put an inference engine on PATH. vLLM is the right engine for safetensors and FP8:
uv tool install vllm # or: pipx install vllmThen install SBproxy itself:
# Linux / macOS, single static binary:
curl -fsSL https://download.sbproxy.dev | sh

# macOS via Homebrew:
brew install soapbucket/tap/sbproxy

# Docker:
docker pull soapbucket/sbproxy:latest
The manual covers checksums, packages, and the rest of the install matrix. SBproxy deliberately does not install engines for you; sbproxy doctor diagnoses a missing one and prints the manual steps.
Minimal config
Save this as sb.yml. It is examples/use-case-serve-on-l4/sb.yml, and its shape comes from examples/ai-local-serving:
proxy:
  http_bind_port: 8080

origins:
  "ai.local":
    action:
      type: ai_proxy
      providers:
        - name: local
          default_model: qwen3-14b
          models:
            - qwen3-14b
          serve:
            models:
              - model: qwen3-14b
                keep_alive: 30m
The proxy block binds the data plane to 8080. The origin key ai.local is the hostname clients address; on a private box a Host: header is enough, and the Terraform demo swaps in a real domain.
The provider is the interesting part. It has no base_url, and that is deliberate: a served provider is hosted on this box, the gateway resolves the engine's loopback port itself, and writing base_url next to serve: is rejected as a config error. The default_model and models list name the serve entry, and that name is the model id every plane sees: routing, budgets, virtual keys, the usage ledger.
Inside serve:, qwen3-14b is a catalog id. The built-in catalog maps it to Qwen/Qwen3-14B and its official quant list, most preferred first: [FP8, Q4_K_M]. The engine defaults to auto (safetensors picks vLLM, GGUF picks llama.cpp), and the fit planner walks the quant list and takes the first one that both runs on the card and fits its free VRAM at the planned context. On this L4 that is FP8. On a 16 GB T4 the same config still works, because the planner refuses FP8 with a capability message and lands on the Q4 GGUF instead. keep_alive: 30m unloads an idle engine after thirty minutes so the VRAM comes back.
To serve GLM instead, change the model line (and the two name references above it) to glm-4-flash, another catalog id. Gemma is not in the built-in catalog and its repos are gated, so give it a model manifest entry instead: one reviewable file that names the source repo, a pinned revision, per-file sha256 digests, a pull policy, and, for a gated repo, your Hugging Face token as an hf_token secret reference rather than a literal in config. Point serve.catalog_file at the manifest and name its entry in serve.models. A curated manifest with digests doubles as a supply-chain allowlist. See examples/model-manifest and the manifest section of model-host.md.
One paragraph on why this config surface is shaped the way it is. Letting configuration start subprocesses inside a gateway that holds provider keys is a real attack surface, so it is constrained: engine is an allowlisted enum (vllm, llama_cpp), never a command string, the runtime owns the argument templates, engine binaries resolve from PATH or pinned releases only, and downloaded weights verify against manifest sha256 digests before an engine reads them. The full posture, including what is enforced today and what hardening remains, is in security-model-host.md.
Run it
Ask the box whether it qualifies before starting anything:
$ sbproxy doctor
build capabilities
  gpu-nvidia      (GPU discovery for serve:)   yes
  model-weights   (managed weight download)    yes
  ...

gpus
  [0] NVIDIA L4  24 GiB total, 22 GiB free, compute 8.9, fp8 yes
  nvidia-smi: /usr/bin/nvidia-smi

inference engines on PATH
  vllm          /home/you/.local/bin/vllm
  llama-server  not found
  container     /usr/bin/docker

model cache
  /var/lib/sbproxy/models (not created yet)

local model serving (serve:): ready
That fp8 yes on the GPU line is the compute capability 8.9 the fit planner gates on. On a machine that does not qualify, the verdict flips to not available and lists every blocker with install steps, which is a better way to find out than a spawn failure at 2am.
Check the config itself with the plan differ. With no --against baseline, everything surfaces as added:
$ sbproxy plan -f sb.yml
  + origins.ai.local [reload] origin 'ai.local' added

Plan: 1 added, 0 changed, 0 removed. max-blast-radius: reload
Exit code 2 means valid with changes present; a config that fails validation exits 3 with the findings printed. The serve-specific rejections are enforced at gateway start, before the listener takes traffic: an engine outside the allowlist (unknown variant 'sglang', expected one of 'auto', 'vllm', 'llama_cpp', 'embedded') or a base_url on a served provider is a fatal boot error with a message naming the fix.
Start the gateway:
sbproxy sb.ymlSend the first completion. Be patient with this one call: it pays the cold start, a managed download of the Qwen3-14B weights into /var/lib/sbproxy/models and a vLLM bring-up. Expect minutes. The gateway log shows the progress.
$ curl -s http://127.0.0.1:8080/v1/chat/completions \
    -H 'Host: ai.local' \
    -H 'Content-Type: application/json' \
    -d '{"model":"qwen3-14b","messages":[{"role":"user","content":"Say hello from the L4."}]}'
{
  "id": "...",
  "object": "chat.completion",
  "model": "qwen3-14b",
  "choices": [{"message": {"role": "assistant", "content": "Hello from the L4!"}, "finish_reason": "stop"}],
  "usage": {"prompt_tokens": 15, "completion_tokens": 7, "total_tokens": 22}
}
Now look at what the fit planner actually decided. The engine argv is built by the runtime, and the quant flag on it is the planner's pick:
$ pgrep -af 'vllm serve'
41217 /home/you/.local/bin/vllm serve Qwen/Qwen3-14B --host 127.0.0.1 --port 8101 --quantization fp8 ...
--quantization fp8 is the decision this page is about, made from the card's compute capability and free VRAM before the process ever spawned. Run the identical config on a T4 and the planner rejects that candidate with FP8 needs FP8 kernels but Tesla T4 (compute 7.5) has none, then falls through to Q4_K_M. The math behind the choice, weights plus KV cache at the planned context times a headroom factor, is in gpu-fit-planning.md.
Send the same request a second time. It answers in normal API time, because the model is resident and stays that way for the keep_alive window.
You are done when
- The completion returns
HTTP 200with an OpenAI-shaped body wheremodelreadsqwen3-14bandusage.total_tokensis present. pgrep -af 'vllm serve'on the box shows--quantization fp8in the engine argv: the fit planner's pick for the Ada card, visible in a process listing.- A second identical request completes in a small fraction of the first call's time.
Then stop the meter:
gcloud compute instances delete sbproxy-l4 --zone=us-central1-a --quietNext steps
self-hosting.md- the wider self-hosting story: cloud spill in the same fallback array, aliasing a hosted model name onto local weights, auth and budgets in frontmodel-host.md- the reference for the catalog, the manifest,keep_aliveand eviction, and the current phase statusgpu-fit-planning.md- the capability tiers and the VRAM math the planner runsmodel-host-certification.md- the certification procedure this page's provisioning steps come from, including the T4 refusal pathsecurity-model-host.md- the threat model for spawning engines from config- AI Gateway - the routing, guardrail, budget, and ledger planes the local model plugs into