Overview
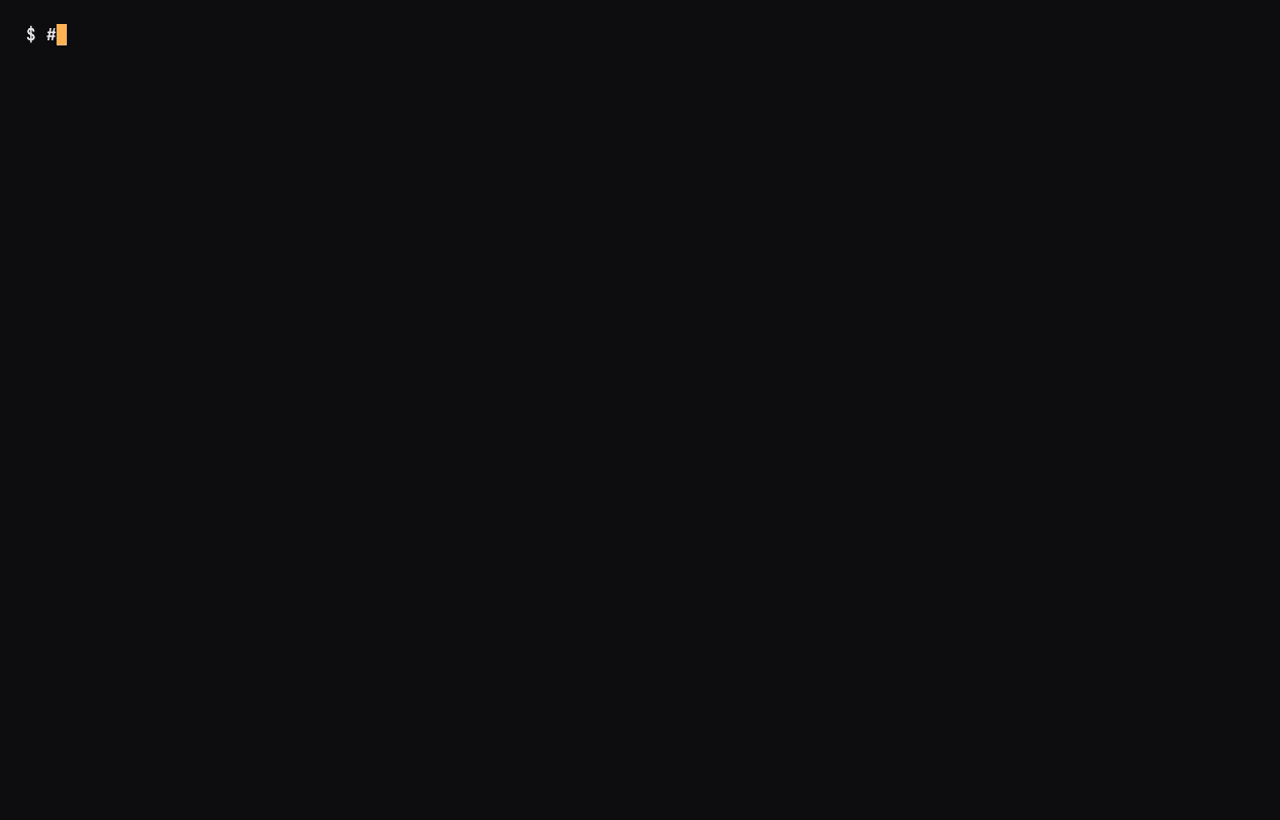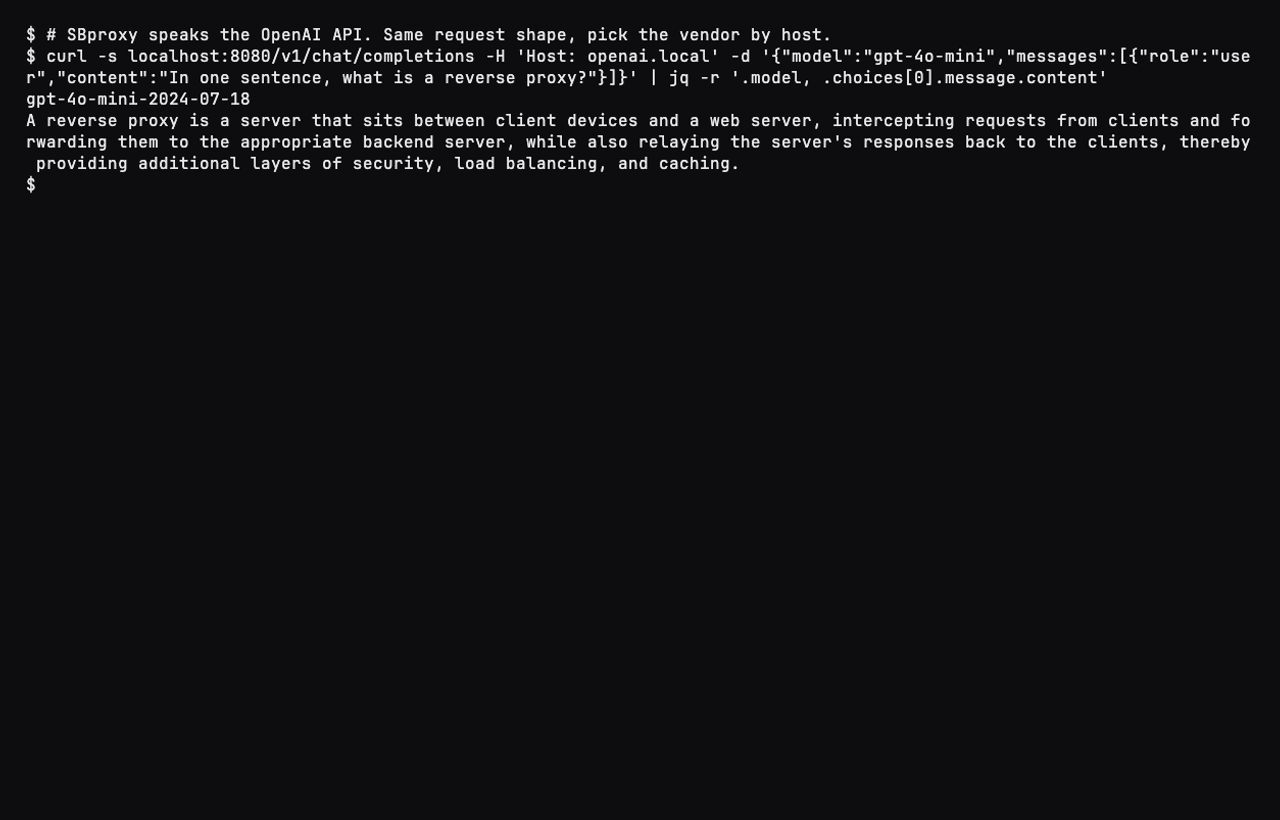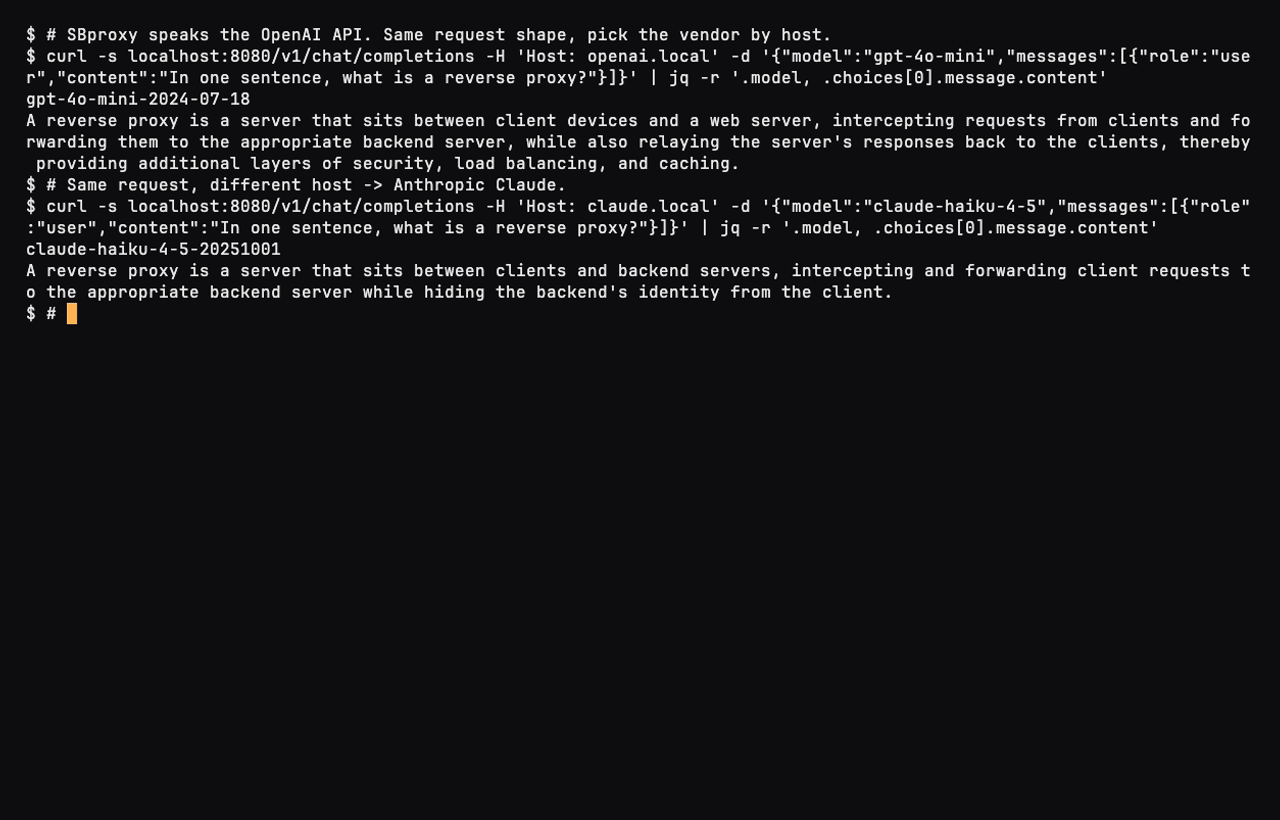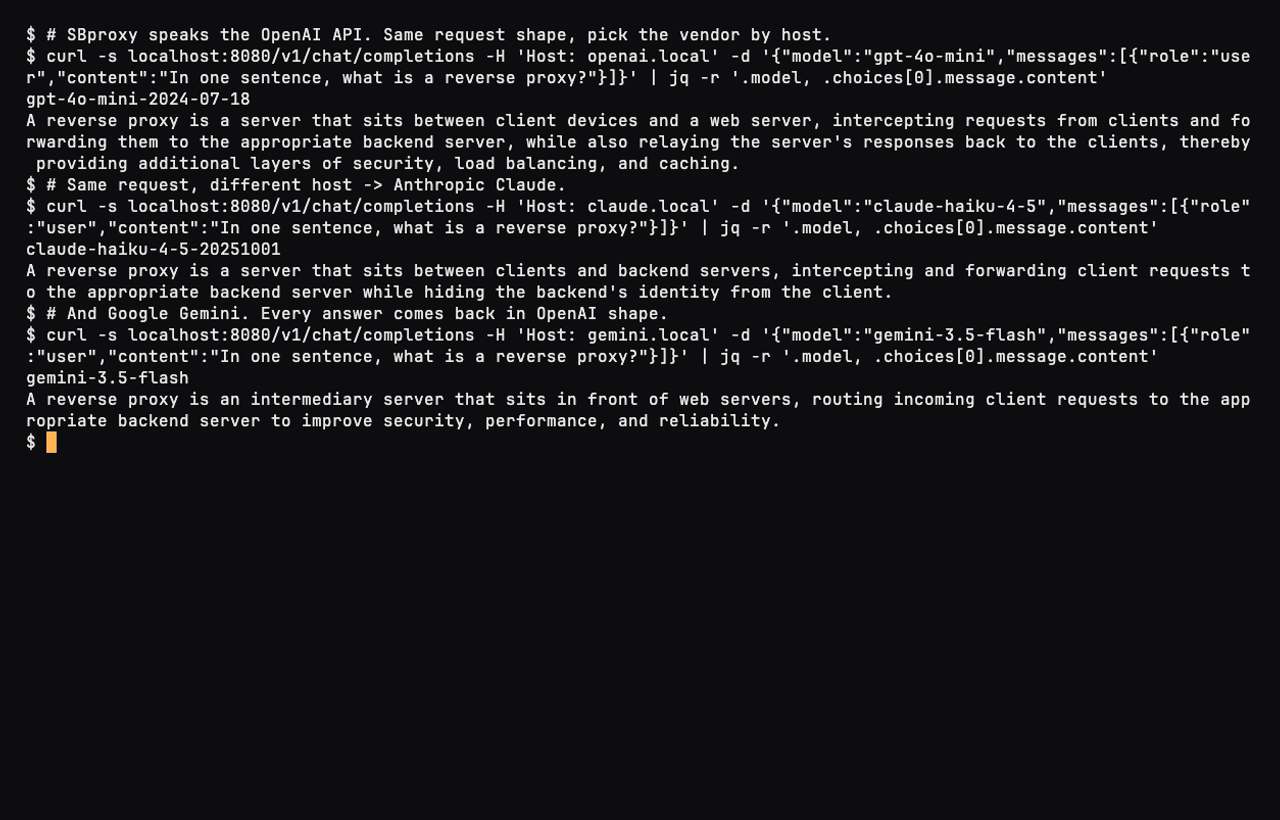
The AI Proxy action type is an AI gateway that reaches 200+ models through 72 native providers (Anthropic, Google Gemini, AWS Bedrock, and more) behind one OpenAI-compatible API, with intelligent routing, load balancing, and failover. You bring your own key per provider and the model name passes straight through, so any model a provider serves works without per-model config. Clients use the OpenAI-compatible API format, and SBproxy handles provider selection, format translation, and error recovery automatically.
Capabilities
- 200+ models - 72 native providers (OpenAI, Anthropic, Google Gemini, AWS Bedrock, Mistral, Azure OpenAI, Azure AI Foundry, Groq, Together AI, Snowflake Cortex, and more) behind one OpenAI-compatible API; bring your own keys
- 15 routing strategies - Round robin, weighted, fallback chain, random, lowest latency, least connections, cost-optimized, token rate, least token usage, prefix affinity, peak EWMA, sticky, race, cascade, and cost/quality
- Per-model rate limits - Set distinct requests-per-minute and tokens-per-minute caps for each model on a provider, matching your provider plan quotas exactly
- Concurrency limits - Cap the number of parallel requests per provider to stay within concurrency ceilings
- Context window safety - Configurable margin that rejects requests exceeding a model's context window before they reach the provider
- Failure mode controls - Choose open (favor availability) or closed (favor safety) behavior when errors occur
- Streaming support - SSE streaming across all providers
- Model mapping - Transparent cross-provider model substitution
- Provider health checks - Proactive monitoring with automatic failover when a provider goes down
- Context window fallbacks - Automatically reroute oversized requests to models with larger context windows
- Cost and usage headers - Every response includes token counts, cost estimates, latency, and provider info
- Request ID tracing - End-to-end request tracking from client through provider and back
- Drop unsupported params - Automatically strip parameters that the target model does not support
Quick Start
Try the AI proxy with the test.sbproxy.dev mock backend (no API key needed):
proxy:
  http_bind_port: 8080

origins:
  "ai.example.com":
    action:
      type: ai_proxy
      providers:
        - name: openai
          api_key: test-key
          base_url: https://test.sbproxy.dev
          models: [test-model]
      default_model: test-model
curl -H "Host: ai.example.com" http://localhost:8080/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{"model": "test-model", "messages": [{"role": "user", "content": "Hello"}]}'Production Example
Multi-provider setup with OpenAI and Anthropic:
proxy:
  http_bind_port: 8080

origins:
  "ai.example.com":
    action:
      type: ai_proxy
      providers:
        - name: openai
          api_key: sk-your-openai-key
          models: [gpt-4o, gpt-4o-mini]
        - name: anthropic
          api_key: sk-ant-your-anthropic-key
          models: [claude-sonnet-4-20250514]
      default_model: gpt-4o-mini
      routing:
        strategy: fallback_chain
sbproxy serve -f sb.ymlRate Limits and Concurrency
Control traffic to each provider with per-model rate limits and concurrency caps:
proxy:
  http_bind_port: 8080

origins:
  "ai.example.com":
    action:
      type: ai_proxy
      providers:
        - name: openai
          api_key: sk-...
          models:
            - gpt-4o
            - gpt-4o-mini
          max_parallel_requests: 50
          max_requests_per_minute: 1000
          rate_limits:
            gpt-4o:
              rpm: 500
              tpm: 40000
            gpt-4o-mini:
              rpm: 2000
              tpm: 200000
      routing:
        strategy: round_robin
        context_window_margin: 0.05
      failure_mode: open
Test rate limits by sending rapid requests:
for i in $(seq 1 10); do
  curl -s -H "Host: ai.example.com" http://localhost:8080/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{"model": "gpt-4o-mini", "messages": [{"role": "user", "content": "Hello"}]}' \
    -w "\nHTTP %{http_code}\n" -o /dev/null
done
Provider-level limits (max_requests_per_minute) apply across all models. Per-model limits (rate_limits) let you set distinct caps per model tier. The most restrictive limit applies. max_parallel_requests caps concurrent in-flight requests independently of rate windows.
The failure_mode field controls what happens when a subsystem like rate limiting encounters an internal error. Set to "open" to allow traffic through, or "closed" to block.