SBproxy includes five scripting engines for custom logic: CEL (Common Expression Language), Rego (via Regorus), Lua, JavaScript, and WASM. The available request context depends on the configuration field; a WASM body transform receives it only with request_context: true.
| Engine | Implementation | Best for |
|---|---|---|
| CEL | cel-rust (the cel crate), with custom SBproxy functions |
Policy gates, routing keys, response header rules |
| Rego | Regorus (Microsoft's Rust interpreter), in process | Policy gates you already have written for OPA |
| Lua | mlua running the Luau runtime, sandboxed |
Header modifiers, JSON body rewriting, WAF custom rules |
| JavaScript | rquickjs (QuickJS), sandboxed with JSON helpers |
JS-native body transforms and response modifiers |
| WASM | wasmtime running WASI preview-1 modules, no filesystem or network |
Polyglot body transforms, untrusted code with strong isolation |
Reach for CEL for one-liner expressions that evaluate in microseconds. Reach for Lua, JavaScript, or WASM when you need variables, loops, helper functions, or multi-step logic.
1. Overview
| Engine | Execution | Isolation |
|---|---|---|
| CEL | Non-Turing-complete expression, compiled once at config load, evaluated per call | No loops, no side effects, no I/O |
| Lua | Interpreted, fresh sandboxed VM per invocation | Globals set by one call never leak into the next |
| JavaScript | QuickJS interpreter, fresh engine per invocation | Dangerous globals removed, CPU/memory/stack caps |
| WASM | Compiled to native via Wasmtime once at config load | Fresh Store per request; module state never leaks |
Lua and JavaScript deliberately build a fresh interpreter state for every invocation so one request's script can never observe another's globals. WASM modules compile once and instantiate per request.
CEL expressions that come from sb.yml are parsed once, while the config compiles, and the request path only evaluates them. That is what makes a CEL syntax error a config error: the proxy refuses to boot on one, and a hot reload carrying one is rejected with the previously active config still serving. It also means a config change is the only thing that can ever reparse an expression. Every CEL surface in the table below works this way.
2. Where scripts are used
| Config field | Engine | Contract |
|---|---|---|
policies[] type: expression, field expression |
CEL | Returns bool; false denies the request with deny_status / deny_message |
policies[] type: assertion, field expression |
CEL | Returns bool at response time; a false assertion is logged and never blocks traffic |
policies[] type: rate_limiting, field key |
CEL | Returns the rate-limit bucket key (e.g. jwt.claims.tenant_id) |
policies[] type: waf, field persistent_block.key |
CEL | Returns the persistent-block tracking key when track_by: cel |
observability.log.custom_fields[] with engine: cel |
CEL | Returns the value of one operator-defined access-log field |
request_modifiers[].lua_script |
Lua | Defines modify_request(req, ctx); returned set_headers are applied to the upstream request |
request_modifiers[].js_script |
JavaScript | Defines modify_request(req, ctx); returned set_headers are applied to the upstream request |
request_modifiers[].rego_module (+ rego_module_path, rego_v0) |
Rego | The data.sbproxy.modify_request rule returns {"set_headers": {...}}, applied to the upstream request |
response_modifiers[].lua_script |
Lua | Defines modify_response(resp, ctx); returned set_headers are applied to the response |
response_modifiers[].js_script |
JavaScript | Defines modify_response(resp, ctx); returned set_headers are applied to the response |
response_modifiers[].rego_module (+ rego_module_path, rego_v0) |
Rego | The data.sbproxy.modify_response rule returns {"set_headers": {...}}, applied to the response |
transforms[] type: lua, field script |
Lua | Defines transform(body, ctx) over the raw body string |
transforms[] type: lua_json, field script |
Lua | Defines modify_json(data, ctx); return value replaces the JSON response body |
transforms[] type: javascript, field script |
JavaScript | Defines transform(body, ctx) over the raw body string |
transforms[] type: js_json, field script |
JavaScript | Defines modify_json(data, ctx) over the parsed JSON body |
transforms[] type: cel, field headers |
CEL | Sets, appends, and removes response headers from CEL |
transforms[] type: wasm, field module_path |
WASM | Body on stdin, transformed body on stdout; request_context: true also carries ctx on an environment variable (costs the transform its response-cache eligibility, see section 6) |
policies[] type: rego, fields module or module_path + query (+ optional data, rego_v0) |
Rego | The queried rule returns bool; false or any fault denies with deny_status / deny_message; data is a JSON object the rule reads as data.<key> |
forward_rules[].rules[].when |
CEL | Boolean predicate over the arriving request; an evaluation error means the rule does not match |
observability.log.custom_fields[] with engine: lua or engine: js |
Lua or JavaScript | Returns the value of one operator-defined access-log field |
policies[] type: waf custom rules |
Lua or JavaScript | Rule script defines match(request); true fires the rule |
origins.<host>.response_cache.key_event, field source |
Lua or JavaScript | Returns {vary, skip_lookup, reason} before the cache lookup; adds dimensions to the cache key |
origins.<host>.response_cache.admit_event, field source |
Lua or JavaScript | Returns {store, ttl_secs, reason} once the response body is complete; decides whether it is stored |
action.ai_policy.expression (in ai_proxy) |
CEL | Returns typed action tokens over the ai.* namespace; see ai-policy-cel.md |
extensions bundle hooks attached as action, policies[], or transforms[] |
JavaScript, load-time TypeScript, envelope WASM, or Rego (policies[] and transforms[]) |
Uses a typed, versioned JSON envelope and the hook's type name; a runtime: rego policy hook reads input.request.* and input.config and returns a Rego boolean, and a runtime: rego transform hook reads input.body.* and input.config and returns a base64 string replacement body (or is undefined to decline) |
origins.<host>.filters[] |
Proxy-Wasm | Runs an ordered Proxy-Wasm ABI 0.2.1 HTTP filter chain |
mcp action federated_servers[].argument_policies[] / result_policies[] |
CEL or Rego | Allow/deny over one tool call's mcp.* context, before dispatch (arguments) and after it (result); see the context note below the table |
federated_servers[] type: local, step condition |
CEL | Boolean gate per DAG step, same mcp.* vocabulary as the argument policies; an expression that fails to evaluate fails the tool call closed (mcp-compose.md) |
federated_servers[] type: local, response: |
Template, JavaScript, or Lua | Shapes the tool result from ctx = {args, steps}, in the same sandboxes the response-cache events run in (mcp-compose.md) |
tool_versioning per-version adapter |
JavaScript | Adapts a caller pinned to an old tool version onto the current contract (tool-versioning.md) |
| Extension AI and payment hooks | JavaScript, envelope WASM, or Proxy-Wasm for AI streaming | Receives provider-neutral, credential-free events through versioned contracts |
For Cedar authorization on federated MCP tools/call, including operator confirmation and offline replay, see Cedar policy. Its entity and context limits differ from the CEL and Rego MCP policies above.
Two AI-gateway surfaces are deliberately not free-form scripting: the ai_policy block is a single CEL expression over gateway-computed signals (ai-policy-cel.md), and guardrails are typed guardrails: input: / output: blocks (injection, pii, jailbreak, toxicity, schema, ...) documented in ai-gateway.md.
Forward rules match with declarative matchers first (method, path, header, query, body) and may add a CEL when: predicate for the conditions those cannot express. See section 3.5 for the shapes and 3.2 for what a when: can read.
3. CEL expressions
CEL is a non-Turing-complete expression language. No loops, no side effects, no I/O. What it does have is fast, safe evaluation of conditions over the request context.
3.1 Context variables
The CEL context is built per request. Every binding below is available to expression policies, which have the widest context of the seven places a config accepts CEL. The others see less, and 3.2 lists exactly what.
Naming a binding your site does not populate is refused when the config loads, so a typo or a copied expression fails at boot with a message naming the site, the binding, and what is available there. Before v1.12 it compiled and then missed at evaluation, which on a rate-limit key: meant every request quietly sharing one __cel_key_error__ bucket.
request - incoming HTTP request
| Field | Type | Description |
|---|---|---|
request.method |
string | HTTP method (GET, POST, etc.) |
request.path |
string | URL path |
request.host |
string | Hostname the request was routed by |
request.headers |
map | Request headers, keys lowercase with hyphens preserved |
request.query |
string | Raw query string (empty string when absent) |
request.time |
int | Wall clock at context build, Unix epoch seconds |
request.unix_nanos |
int | Same instant in epoch nanoseconds |
request.agent_id |
string | Resolved agent identifier (human, anonymous, unknown, or a catalog id like openai-gptbot) |
request.agent_class |
string | Alias of agent_id: the catalog id is the class |
request.agent_vendor |
string | Operator display name (OpenAI, Google, ...) |
request.agent_purpose |
string | Operator-stated purpose (training, search, assistant, ...) |
request.agent_id_source |
string | Which resolver signal matched (bot_auth, rdns, user_agent, anonymous_bot_auth, fallback) |
request.agent_rdns_hostname |
string | Forward-confirmed reverse-DNS hostname when the rDNS path matched |
request.trust_tier |
string | Conservative identity tier: suspicious, strong, named, or anonymous |
request.aipref.train |
bool | Parsed aipref: header, training axis (default true) |
request.aipref.search |
bool | Search axis (default true) |
request.aipref.ai_input |
bool | Inference-input axis (default true) |
request.tls.ja3 / request.tls.ja4 / request.tls.ja4h |
string | TLS fingerprints, "" when unavailable |
request.tls.trustworthy |
bool | Whether the fingerprint reflects the actual client |
request.headless_signal.detected |
bool | Whether the JA4 headless-browser detector matched |
request.headless_signal.library |
string | Library label (puppeteer, playwright, ...) or "" |
request.headless_signal.confidence |
double | Detector confidence in [0.0, 1.0] |
Header normalization: header keys are lowercased only; hyphens are preserved. Always use bracket notation:
request.headers["content-type"], notrequest.headers["Content-Type"]orrequest.headers.content_type.
request.kya.* (Know-Your-Agent verifier verdict) and
request.ml_classification.* (ML agent classifier verdict) are available when their
respective subsystems run.
The trust tier is computed once after identity enrichment and authentication.
An observed denial wins over positive evidence; verified Web Bot Auth, CAP,
KYA, or another signed agent verdict is strong; a sufficiently confident
unsigned rule-pack identity is named; and missing evidence is anonymous.
For example:
request.trust_tier == "strong" || request.trust_tier == "named"
connection - peer information
| Field | Type | Description |
|---|---|---|
connection.remote_ip |
string | Client IP address, when known |
jwt - decoded Authorization Bearer claims
| Field | Type | Description |
|---|---|---|
jwt.claims |
map | Claims from Authorization: Bearer <jwt>, decoded but not signature-verified. Empty map when no header, no Bearer prefix, fewer than three segments, or non-object payload. |
jwt.claims is for keying and routing decisions (rate-limit buckets, route gates). It is not an authentication boundary. Signature verification stays with the jwt auth provider configured under authentication:. A common pattern: gate the route with authentication: jwt, then key the rate limiter on jwt.claims.tenant_id using the same token.
# Rate-limit by tenant: each tenant_id gets its own bucket.
key: 'jwt.claims.tenant_id'

# Composite key: per-user inside per-tenant.
key: 'jwt.claims.tenant_id + ":" + jwt.claims.sub'
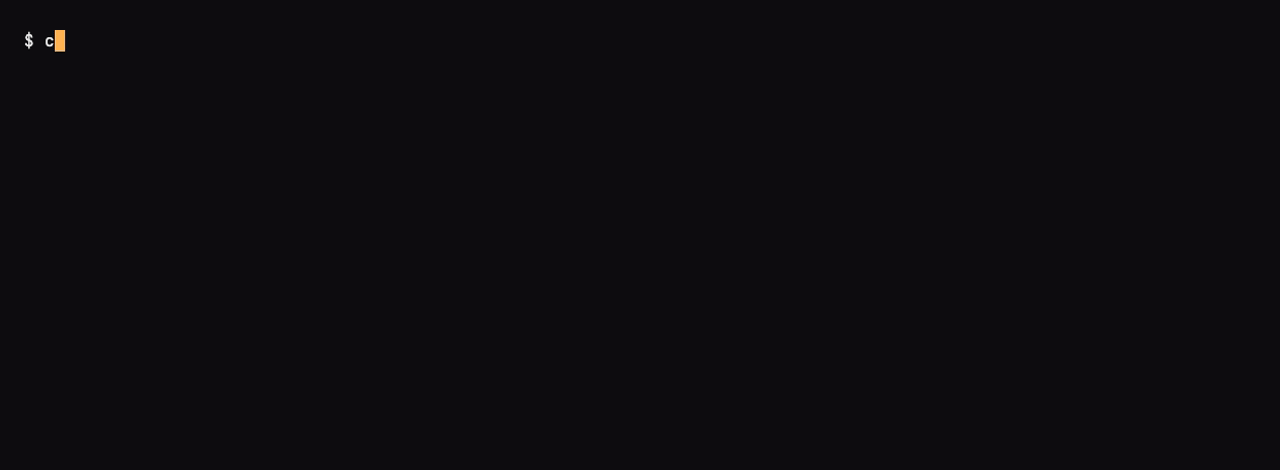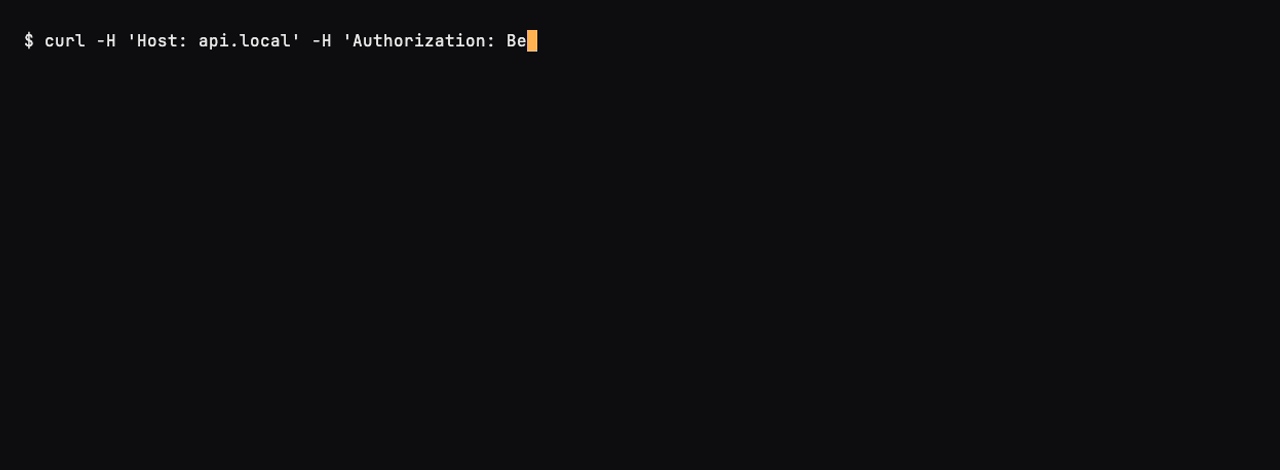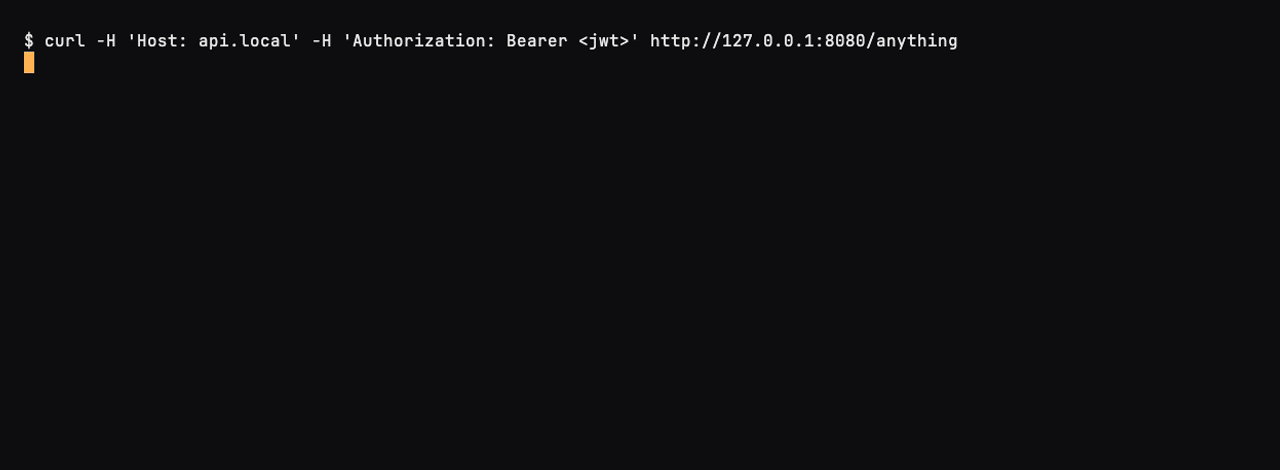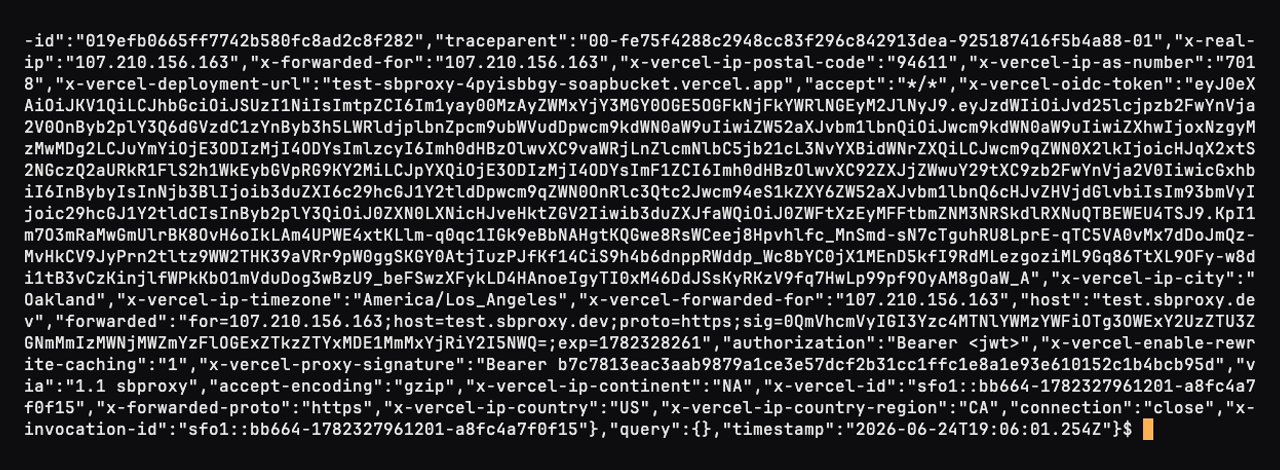
When the claim expression comes back empty the limiter falls back to client IP (config).
agent - resolved agent class
A top-level alias namespace for the request.agent_* fields, for cleaner expressions.
| Field | Type | Description |
|---|---|---|
agent.id |
string | Resolved agent identifier |
agent.class |
string | Alias of agent.id |
agent.vendor |
string | Operator display name |
agent.purpose |
string | Operator-stated purpose |
agent.source |
string | Resolver signal that matched |
agent.rdns_hostname |
string | rDNS hostname when the rDNS path matched |
envelope - capture envelope dimensions
| Field | Type | Description |
|---|---|---|
envelope.user_id |
string | Resolved user identifier |
envelope.user_id_source |
string | Where user_id came from (header, jwt, forward_auth) |
envelope.session_id |
string | Session identifier |
envelope.parent_session_id |
string | Caller-supplied parent session |
envelope.workspace_id |
string | Tenant scope |
envelope.properties |
map | Custom properties captured at request entry |
principal - unified caller identity
| Field | Type | Description |
|---|---|---|
principal.tenant_id |
string | Tenant the request resolved to |
principal.sub |
string | Subject identifier (JWT sub, virtual-key name, basic-auth username) |
principal.source |
string | Provider slug (bearer, api_key, virtual_key, ...) |
principal.virtual_key |
map | { name, allowed_providers: [...] }, empty fields when no virtual key matched |
principal.attrs.project |
string | Attribution: project |
principal.attrs.user |
string | Attribution: user |
principal.attrs.team |
string | Attribution: team |
principal.attrs.tags |
list | Operator-supplied tags |
principal.attrs.metadata |
map | Metadata fan-out |
principal.attrs.roles |
list | Roles claimed by the principal |
principal.claims |
map | Verbatim claims map when JWT or OIDC auth stamped them |
features - per-request feature flags
| Field | Type | Description |
|---|---|---|
features.debug |
bool | Built-in debug flag |
features.trace |
bool | Built-in trace flag |
features["no-cache"] |
bool | Built-in no-cache flag (bracket access: hyphens are not valid CEL identifiers) |
features.any_set |
bool | True when any flag, built-in or extra, is set |
features["<key>"] |
string | Free-form k=v flag entries; unset keys render as "" |
response - response data (response-time evaluation only)
| Field | Type | Description |
|---|---|---|
response.status |
int | HTTP status code |
response.headers |
map | Response headers, lowercase keys |
response.body_size |
int | Response body size in bytes, when known |
The response namespace is available where CEL runs at response time: assertion policies and the cel transform. In the cel transform the namespace is split by phase, and no phase binds all of it: an origin whose action streams an upstream response binds response.status and response.headers and has no body yet, and an origin whose action buffers its whole response binds response.status and response.body and does not yet own a response header map. See the phase table in 3.6.
Within a populated namespace, missing fields render as zero values ("", 0, false, empty map), so expressions like size(request.agent_id) > 0 work without probing for presence first. A namespace whose subsystem never ran for the request (for example request.tls on a plain HTTP listener) may be absent entirely; guard those accesses or accept the fail-closed deny.
3.2 What each config site offers
Seven places in a config take a CEL expression, and they do not all see the same context. A transform: cel runs after the headless detector, so it gets request.headless_signal; a policy: expression runs before the response exists, so it has no response.
| Binding | policy: expression |
policy: assertion |
transform: cel |
rate_limit.key |
custom_log field |
waf track_by: cel |
forward rule when |
|---|---|---|---|---|---|---|---|
request.method, .path, .host, .query, .headers |
yes | yes | no | yes | yes | yes | yes |
request.time, .unix_nanos |
yes | yes | no | yes | no | yes | yes |
connection.remote_ip |
yes | yes | no | yes | no | yes | yes |
jwt.claims |
yes | yes | no | yes | no | yes | yes |
request.trust_tier |
yes | yes | no | no | no | no | no |
request.tls |
yes | no | yes | no | no | no | no |
request.agent_class and the other agent_* scalars |
yes | no | yes | no | no | no | no |
request.agent (detector map: .score, .headless_score, ...) |
yes | no | no | no | no | no | no |
agent |
yes | no | yes | no | no | no | no |
request.aipref |
yes | no | no | no | no | no | no |
request.kya |
yes | no | no | no | no | no | no |
request.ml_classification |
yes | no | no | no | no | no | no |
principal |
yes | no | no | no | no | no | no |
request.headless_signal |
no | no | yes | no | no | no | no |
response |
no | yes | yes | no | response.status only |
no | no |
features |
yes | no | no | yes | no | yes | no |
envelope |
no | no | no | yes | no | yes | no |
request.key_id |
no | no | no | yes | no | yes | no |
tenant_id, provider, model, tokens_in, tokens_out, client_ip, attribution |
no | no | no | no | yes | no | no |
Three columns are easy to misread.
The transform: cel column has no request bindings at all, which surprises people. A response transform builds its request half from placeholders rather than from the request, so request.method there would always read "GET" no matter what the client sent. Rather than hand you a binding that quietly lies, the config refuses it. If you need to branch a response header on the request, decide it in a policy: expression and carry the result forward.
The custom_log column looks eccentric because it is. That site builds its own context rather than sharing the request builder, which is why it is the only one with attribution and token counts, and the only one whose request has no time. Treat it as its own vocabulary.
The waf column is identical to rate_limit.key because both run through the same evaluator. If you are keying a persistent block, write it as you would a rate-limit key.
The forward-rule column is the narrowest, and deliberately so. A forward rule matches during routing, before authentication, identity enrichment, the TLS fingerprint pass, and the classifiers have run, so none of what those produce exists yet. It sees the request as it arrived.
A when: is ANDed with the structured matchers in the same entry and evaluated last, so a rule that fails a cheap path check never pays for it. Use it for what the structured fields cannot say, which is OR, negation, and comparisons across two parts of the request:
forward_rules:
  - rules:
      - header:
          name: x-tenant
          value: acme
        when: '!request.path.startsWith("/internal/")'
    origin:
      action:
        type: proxy
        url: https://acme.test.sbproxy.dev
That one is not expressible without it. Entries in a rules: list OR, and matchers inside one entry AND, so a plain OR across two paths is already two entries and does not need CEL. What has no structured form is the negation above, and comparisons that draw on two different parts of the request at once.
A predicate that fails to evaluate does not match, and the rule is skipped. Routing past a gate an operator wrote would be the worse failure.
Two related surfaces are not in the table. ai_policy.expression evaluates over a single ai namespace and is documented in ai-policy-cel.md; it does not share this context, and its expressions are checked at config load against that one-namespace vocabulary rather than this table. An mcp action's argument_policies[] and result_policies[] are the same shape, over a single mcp namespace (mcp.tool.name, mcp.server, mcp.session.id, mcp.session.integrity, mcp.session.sensitive_touched, mcp.arguments, mcp.result, mcp.tenant, mcp.principal.{sub,team,project,user}), evaluated against one call's tool-call context; argument_policies[] runs after RBAC and JSON-Schema validation pass, before dispatch, and mcp.result reads as null there (no result exists yet); result_policies[] runs after dispatch and after content_filters, against the tool-call result document, with mcp.result bound to it and mcp.arguments still readable alongside it so a rule can correlate a result with the call that produced it. See mcp-security.md. mcp.session.integrity and mcp.session.sensitive_touched are the deterministic session-flow labels (Meta's Rule of Two) the flow guardrail maintains (trusted/tainted, and a sticky bit for whether the session has touched sensitive-labeled data); a rule reads them to compose a policy flow's own built-in two_of_three/taint_and_outbound rules do not express. Both engine: cel and engine: rego read the same context, so mcp.tool.name in CEL is input.mcp.tool.name in Rego.
A binding marked no is refused when the config loads, whether you write it as request.trust_tier or as request["trust_tier"]. The message names the site and lists what that site does provide, so the fix is usually visible without opening this page:
origin `api`: invalid policy config

Caused by:
    policy `expression`: expression "request.headless_signal.detected" references
    request.headless_signal, which policy `expression` does not provide. Available
    here: agent, connection.remote_ip, features, jwt.claims, principal,
    request.agent, request.agent_class, ..., request.unix_nanos
3.3 Built-in functions
CEL includes the standard operators (+, -, *, /, %, in, ==, !=, <, >, <=, >=, &&, ||, !) and the cel crate's stock helpers such as contains, startsWith, endsWith, and size. SBproxy registers these additional functions on every evaluation context:
| Function | Returns | Description |
|---|---|---|
ip_in_cidr(ip, cidr) |
bool | True if ip falls within cidr (e.g. "10.0.0.0/8"); false on unparseable input |
uuid_v4() |
string | Random UUID v4 |
now() |
string | Current UTC time as an RFC 3339 string |
sha256(s) |
string | SHA-256 hex digest of s |
base64_encode(s) |
string | Standard base64 encoding |
base64_decode(s) |
string | Standard base64 decoding; errors on invalid input |
regex_match(s, pattern) |
bool | True if s matches pattern. Patterns over 1024 bytes or that exceed the compile size limit are rejected (returns false, logs a warning) |
s.toLowerCase() |
string | Lowercase |
s.toUpperCase() |
string | Uppercase |
s.trim() |
string | Trim leading and trailing whitespace |
s.split(sep) |
list | Split s on sep |
flag_enabled(name, key) |
bool | Resolve a feature flag against the live flag store; unknown flags evaluate false |
tls_fingerprint_matches(ja4, agent_class_id) |
bool | True when ja4 is a known fingerprint for the cataloged agent class, or when the catalog has no entry for the class (conservative) |
flag_enabled reads the process-wide set declared by the top-level flags: block. Its second argument is the stable bucketing key; use a user, tenant, or subject identifier rather than a random request ID. Successful hot reloads replace the full flag set atomically, and an absent flags: block clears it. Unknown flags evaluate to false. See Edge feature flags for the rule grammar.
3.4 CEL policy examples
The scripted request gate is the expression policy. It takes one CEL expression; false (or an evaluation error) denies the request with deny_status (default 403) and deny_message.
The expression is compiled once, when the config compiles. An expression that does not parse rejects the whole config: at boot the proxy refuses to start, and on a hot reload the candidate config is rejected and the previously active config keeps serving traffic. The error names the origin, the policy, and the bad expression. At request time only evaluation can fail, and an evaluation error (a missing map key, a non-boolean result) denies the request: the expression could not prove the request is allowed.
Gate a route on a header value
origins:
  "cel.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    policies:
      - type: expression
        expression: 'request.headers["x-tenant"] == "acme"'
        deny_status: 403
        deny_message: "tenant not allowed"
API traffic only, specific methods
policies:
  - type: expression
    expression: 'request.path.startsWith("/api/") && request.method in ["GET", "POST"]'
    deny_message: "only GET/POST under /api/"
Requests from a CIDR range
policies:
  - type: expression
    expression: 'ip_in_cidr(connection.remote_ip, "10.0.0.0/8")'
    deny_status: 403
    deny_message: "internal network only"
JWT-claim role gate
policies:
  - type: expression
    expression: '"admin" in principal.attrs.roles || jwt.claims.role == "admin"'
    deny_status: 403
    deny_message: "admin role required"
Block traffic that opted out of training
policies:
  - type: expression
    expression: 'request.aipref.train || request.headers["x-research-license"] != ""'
    deny_message: "Training use requires aipref: train=yes or a research license header."
Agent-class gate with TLS fingerprint check
policies:
  - type: expression
    expression: >
      request.agent_id != "openai-gptbot" ||
      tls_fingerprint_matches(request.tls.ja4, request.agent_id)
    deny_status: 403
    deny_message: "fingerprint does not match claimed agent"
Rate limiting keyed on a claim
policies:
  - type: rate_limiting
    requests_per_minute: 100
    burst: 20
    key: 'jwt.claims.tenant_id'
The full working config is in examples/ratelimit-by-claim/.
The key: expression compiles with the config, so a syntax error in it refuses the config the same way an expression policy does. At request time, an expression that evaluates to null or an empty string means "no key for this request" and the request falls back to the default client key (client IP, or the hostname when no client IP is known). An expression that fails to evaluate is different: the request is bucketed under a __cel_key_error__: prefix on the default client key, and the failure is logged. Rate limiting stays on either way, and error traffic never shares a bucket with correctly keyed traffic.
Response assertions
The assertion policy (alias response_assertion) evaluates CEL against the response and logs the verdict. It is observational: a false assertion never changes the response, and never blocks traffic.
policies:
  - type: assertion
    name: no-5xx
    expression: 'response.status < 500'
The expression compiles with the config, so a syntax error refuses the config. This matters more here than the log-only framing suggests: before, a mis-typed assertion parsed at response time, failed, and was skipped, so the check the operator wrote never ran and nothing said so.
At response time an evaluation error (a key the response did not carry, a result that is not a boolean) is logged and recorded as a pass. Nothing branches on the verdict, so recording a failure would put a line in the log claiming an assertion failed when it never ran.
The Go-compatible shape is accepted too, and compiles the same way:
policies:
  - type: response_assertion
    assertions:
      - name: no-5xx
        cel_expr: 'response.status < 500'
        action: pass
3.5 Forward-rule matchers
Forward rules dispatch to inline child origins with declarative matchers, evaluated in order with first match winning. Each entry in a rule's rules: list may carry a method, path, header, query, and body matcher; matchers present in one entry are ANDed, entries in the list are ORed.
An entry may also carry a CEL when:, ANDed with the rest and evaluated last. Reach for it when a condition needs OR, negation, or a comparison across two parts of the request, which the structured matchers cannot express no matter how many of them are added. Its bindings are in 3.2, and they are the narrowest of any surface because routing runs before the rest of the pipeline.
origins:
  "gateway.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    forward_rules:
      # Path prefix.
      - rules:
          - path:
              prefix: /api/
        origin:
          action:
            type: proxy
            url: https://api-backend.internal

      # Exact path.
      - rules:
          - path:
              exact: /healthz
        origin:
          action:
            type: static
            status: 200
            content_type: text/plain
            body: ok

      # Template with named segments and a per-segment constraint.
      - rules:
          - path:
              template: /users/{id:[0-9]+}/posts/{post_id}
        origin:
          action:
            type: proxy
            url: https://posts-backend.internal

      # Whole-path regex escape hatch.
      - rules:
          - path:
              regex: '^/v[0-9]+/reports/.*$'
        origin:
          action:
            type: proxy
            url: https://reports-backend.internal

      # Header AND query in one entry.
      - rules:
          - header:
              name: X-Beta-User
              value: "true"
            query:
              name: env
              value: staging
        origin:
          action:
            type: static
            status: 200
            content_type: application/json
            body: '{"beta": true}'
The shorthand match: /api/ on an entry is equivalent to path: { prefix: /api/ }. Header matchers take name plus either value (exact) or prefix; header name lookup is case-insensitive, value comparison is case-sensitive. Query matchers take name and an optional exact value; with no value, parameter presence is enough. Template captures surface as path_params on the request context.
There is no lua: matcher inside forward rules, and the CEL one is when: above. For a condition needing a binding routing does not have, such as a trust tier or a classifier verdict, gate with an expression policy instead: those run after the passes that produce it.
3.6 The cel response transform
The cel transform is the CEL surface on the response path. It sets, appends, or removes response headers via per-header rules with value_expr CEL expressions.
origins:
  "api.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    transforms:
      - type: cel
        headers:
          - { op: set, name: x-served-by, value_expr: '"sbproxy"' }
          - { op: set, name: x-upstream-status, value_expr: 'string(response.status)' }
          - { op: remove, name: x-internal-trace }
Each value_expr sees response.status and the request.* namespace, plus whichever of response.headers and response.body its phase binds (below). A string result is used verbatim; ints, floats, and bools render as strings; maps and lists are JSON-serialized; null skips the rule. Set-Cookie is on a deny-list: a CEL header rule cannot set it.
op: set replaces every existing value of that header, op: append adds one beside them, and op: remove drops them all. The three mean the same thing on every action type.
Which phase a rule runs in. A header rule can only change a header while the header map is still yours to change, and that moment is different for a response streamed from an upstream than for one sbproxy writes itself. Envoy and Kong draw the same line: a header filter runs before the body exists, and a body filter runs after the headers are gone. The consequence worth reading twice is that no phase binds the whole response.
| Origin's action | Phase the rules run in | response.status |
response.headers |
response.body |
|---|---|---|---|---|
proxy, load_balancer, a2a |
Response header phase, before the first body byte arrives | upstream status | upstream headers | not available |
static, mock, plugin |
After the whole response is buffered and before any of it is written | the status the action produced | not available | the whole body |
echo, beacon, redirect, storage, noop, mcp, grpc, graphql, ai_proxy, websocket |
None. These settle the request without running the origin's transform chain at all | not available | not available | not available |
Three rules follow from the table, and each is enforced rather than documented:
- A rule evaluates exactly once, in one phase. A streaming origin evaluates in the header phase and applies the mutation there; the later body-buffer stage does not evaluate again.
- A rule that reaches for what no route on its origin can bind is refused when the config compiles, naming the origin, the rule, and the action.
response.bodyon an origin every route of which streams;response.headerson an origin every route of which buffers; any header rule at all on an origin whose action is in the third row and which has no forward rule in the first two. Set a constant or request-derived header on a third-row action with aresponse_modifiers:entry instead. - A rule the config accepts, but that this particular route cannot serve, is skipped and counted. One origin can serve two routes in different phases: a
proxyorigin with astaticforward rule buffers on/local/and streams everywhere else. The route that can bind what the rule reads runs it; the route that cannot skips it and tickssbproxy_errors_total{error_type="response_body_unavailable"}or{error_type="response_headers_unavailable"}, with aWARNnaming the rule. It never resolves against an empty body or an empty header map.
The compile refusal reads the expression as written. It sees response.body, response["body"], response['body'], and the same three forms for headers, with whitespace anywhere between the tokens, and it does not mistake a name inside a string literal for a reference. It cannot see a reference reached through a cel.bind alias or assembled by string concatenation; those reach the runtime, where the phase that cannot bind the value resolves it to an empty one.
Every value_expr is compiled when the config compiles. A syntax error refuses the config, naming the origin and the header the expression belongs to. Responses then only evaluate.
CEL decides, it does not produce. This transform cannot write a response body, and two removed keys are refused at config compile rather than ignored:
| Removed key | Why | Reach for instead |
|---|---|---|
on_request: |
Compiled at config load and never evaluated. Every transform here is response-side: the dispatch signature is (body, content_type) and it runs off the response body buffer, so there was no request phase for the expression to run in. |
An expression policy to gate the request, a rate-limit or WAF key: expression to key on it, or a forward rule to route on it. |
on_response: (alias expression:) |
Replaced the entire response body with whatever scalar the expression evaluated to. No partial edit, no structure-aware change, no streaming. That is producing output, which is a different job from deciding. | A javascript, lua_json, or WASM transform. Each parses the body, edits part of it, and re-emits. |
At response time the posture is deliberately forgiving, because the response is already on its way out: a header rule whose expression fails is skipped, the rest of the chain still runs, and the failure is logged.
3a. Rego policies
policy: rego evaluates a Rego module against the same request context a policy: expression sees. It exists for one reason: some teams already have Rego, and rewriting a working policy set is worse than running it. If you are writing a new policy from scratch, prefer expression; the reasons are below and they are not stylistic.
policies:
  - type: rego
    module: |
      package sbproxy

      default allow := false

      allow if {
        input.request.trust_tier == "strong"
      }

      allow if {
        input.request.method == "GET"
        startswith(input.request.path, "/public/")
      }
    # Optional. Defaults shown.
    query: data.sbproxy.allow
    deny_status: 403
    deny_message: forbidden by policy
    budget_ms: 50
What input contains
The exact binding set of policy: expression in the table above, converted to JSON. request.trust_tier in CEL is input.request.trust_tier in Rego; both engines read the same assembled context, so the vocabulary cannot drift between them. A decision is portable in both directions by translating syntax alone, with two exceptions below.
input.jwt.claims deserves the same warning it carries on the CEL side, and it matters more here because Rego is what people reach for to write authorization: the claims are decoded, not verified. input.jwt.claims.role == "admin" trusts whatever the client sent. Signature verification belongs to the jwt auth provider under authentication:; gate the route there first, then use the claims for authorization.
Base data: the table the rule reads
Rego splits what a policy decides from the data it decides against: the rule is input, the reference data is data. policy: rego carries that split with an optional data field, a JSON object the rule reads as data.<key>:
policies:
  - type: rego
    module: |
      package sbproxy
      default allow := false
      allow if { input.request.method == data.allowed_methods[_] }
    data:
      allowed_methods: ["GET", "HEAD"]
The point is that the allowlist, role table, or routing map lives in its own config value, separate from the module. An operator edits data.allowed_methods without reading a line of Rego, and the policy logic never changes when the table does. data must be a JSON object (the rule indexes into it by key), and it is capped at one megabyte serialized: base data is a config-embedded table, not a bulk dataset, and a document that large belongs behind a data source rather than inline. Because data is ordinary config, editing it is a config change like any other, applied on the next reload.
A data key may not collide with any rule the module defines. Rego resolves the base document over a rule's own value at the same path, and it does so per rule rather than per query. A data of {sbproxy: {allow: true}} under a data.sbproxy.allow query overrides the allow rule outright, and a data of {sbproxy: {trusted: true}} overrides a trusted helper that allow reads, which is worse: the query still evaluates, the decision still looks computed, and the rule that stopped running says nothing about having stopped. A deny rule shadowed that way fails open.
So the config is refused at load rather than warned about at request time, and the refusal covers every rule head in the module, not just the one the query names:
policy `rego`: base data defines `data.sbproxy.trusted`, and the module defines a rule at
that path, so Rego resolves the base document there and the rule never evaluates. The query
`data.sbproxy.allow` reaches it: data.sbproxy.allow -> data.sbproxy.trusted. Move the base
data under a key no rule in the module produces.
The three shapes that refuse:
| Base data | Rule the module defines | Why |
|---|---|---|
data.sbproxy.allow |
data.sbproxy.allow |
Same path. The rule never contributes a value; null counts as a value here. |
data.sbproxy.allow.reason |
data.sbproxy.allow |
Defining something under the rule's path defines the rule's path. |
data.sbproxy set to a scalar |
data.sbproxy.allow |
A non-object above a rule leaves the rule nowhere to resolve. |
A partial rule (limits[method] := ...) is the one shape the check cannot compare precisely. When the rule produces a GET key, Rego indexes data.sbproxy.limits.GET, one segment deeper than anything the source names, so which base keys collide depends on values the rule computes per request. Load time sees only data.sbproxy.limits, and three outcomes follow from what sits there:
Base data at data.sbproxy.limits |
Result |
|---|---|
| Absent, or an empty object | Loads. An empty object holds no key that can beat a computed one. |
| An object with any key | Refused. Every key the base document carries wins over the rule's, and load time cannot tell a key the rule produces from one it never will. |
| A scalar | Refused. No key the rule produces has anywhere to land; Regorus otherwise reports this mid evaluation as previous value is not an object. |
The middle row refuses configs that would have worked. Base data of {sbproxy: {limits: {POST: "no"}}} beside a rule that only ever produces GET merges cleanly in Rego, and it now refuses at load. The trade is deliberate: being wrong the other way is silent, shows up as a rule that stopped contributing its key, and fails open, while this refusal arrives at boot and is fixed by moving the table. The message for this shape says the base keys win rather than saying the rule never evaluates, because the second claim is not one the check can make.
A function that takes parameters (permitted(method)) is not stored under data and cannot be shadowed. A function with no parameters (audit_enabled()) is stored under data and is shadowed exactly like a rule.
What still loads is a sibling: an object at data.sbproxy holding keys no rule produces, like data.sbproxy.roles next to an allow rule, merges with the rules beneath it and is the intended way to carry a table inside the package namespace. Keeping the table at the top level, the way data.allowed_methods does above, avoids the question entirely.
The two things Rego does not inherit
Typos are not caught at config load. A CEL expression naming a binding its surface does not provide is refused when the config loads. Rego cannot offer that: input.request.trust_teir is not an error, it is undefined, which is a value the language is designed to reason about. A misspelled binding is a rule that never fires, discovered from traffic behavior rather than from an error message. This is the strongest reason to prefer expression when either engine would do.
The SBproxy helper functions do not exist in Rego. flag_enabled() and tls_fingerprint_matches() have no Rego equivalent; a policy needing either belongs in expression. The generic helpers have standard Rego analogs: ip_in_cidr is net.cidr_contains, sha256 is crypto.sha256, regex_match is regex.match.
Failure posture
Everything fails closed, at the earliest point it can be detected:
| Fault | When it is caught | What happens |
|---|---|---|
| Module does not parse | config load | config refused, boot and reload both name the error |
Module parses but is semantically invalid (unsafe variable, query naming no rule) |
config load | config refused; the engine runs one trial evaluation so deferred analysis cannot push an authoring mistake to request time |
Load-time trial exceeds budget_ms |
config load | compile proceeds; the trial is inconclusive, not a semantic fault. The same budget still denies at request time |
Rule errors, returns a non-boolean, or exceeds budget_ms at request time |
per request | request denied with deny_status, one warning logged |
budget_ms bounds one evaluation's wall clock and defaults to 50ms, matching the extension-bundle sandbox. It cannot be zero.
One OPA divergence worth knowing
Builtin errors are strict here. Upstream OPA treats a builtin error as undefined and moves on; Regorus propagates it, and this surface turns it into a denial. A policy that leans on that forgiveness upstream, for example calling net.cidr_contains on a header that is sometimes not a CIDR, works on OPA and denies here. Guard the input first, or accept the deny.
module_path: a .rego file instead of an inline string
module and module_path are mutually exclusive; exactly one must be set. module_path is a filesystem path to a .rego file, read once when the config compiles (and again on every reload, since a reload recompiles the whole config), resolved relative to the proxy's working directory. It exists for the same reason transforms[] type: wasm's module_path does: real policy lives in source control as its own file, not pasted into a YAML block scalar.
policies:
  - type: rego
    module_path: /etc/sbproxy/policies/authz.rego
    query: data.sbproxy.allow
The loaded text feeds the same compile path an inline module does, so everything above (base data, failure posture, the OPA divergence) applies identically either way.
rego_v0: pre-OPA-1.0 syntax
Regorus, like current OPA, defaults to Rego v1: rule bodies require if, and multi-value rules require contains. A module written before OPA 1.0 (December 2024) uses the older syntax, allow { ... } with no if, and fails to parse under the default. rego_v0: true (default false) calls Regorus's own v0 compatibility switch before parsing, so that module compiles unchanged:
policies:
  - type: rego
    rego_v0: true
    module: |
      package sbproxy

      allow {
        input.request.method == "GET"
      }
Reach for it to run a policy pasted from an older OPA install rather than rewriting it; a module authored fresh should use if/contains and leave the flag at its default.
print() capture
A print() call inside a policy never reaches the process's stderr. It is gathered per evaluation and logged through tracing at INFO under the rego_print target, one event per call, carrying the policy's site, its query, and the tenant the evaluated request resolved to (empty when none). Nothing needs to be configured; this is the default behavior of Rego evaluation itself, not something each call site opts into, so it covers every surface that compiles a Rego module: policy: rego, ai_routing_policy engine: rego, a request/response modifier's rego_module, and a signed extension bundle's runtime: rego policy and transform hooks.
Rego modifiers
request_modifiers[] and response_modifiers[] also accept a Rego form, beside lua_script and js_script: rego_module (inline source) or rego_module_path (a path to a .rego file, mutually exclusive with rego_module), rego_v0 for pre-OPA-1.0 syntax, and rego_budget_ms (default 50, must be greater than zero) for the evaluation budget, the same knob policy: rego and ai_routing_policy's Rego form expose. This is engine-surface parity, not a different contract: the module evaluates against the same document req/resp and ctx give Lua and JavaScript, merged into one input because Rego takes a single document where the other two take two arguments, and it returns the same {"set_headers": {...}} shape those scripts return.
request_modifiers:
  - rego_module: |
      package sbproxy

      default modify_request := {"set_headers": {"x-caller-kind": "browser"}}

      modify_request := {"set_headers": {"x-caller-kind": "crawler"}} if {
        contains(input.request.headers["user-agent"], "GPTBot")
      }
response_modifiers:
  - rego_module: |
      package sbproxy

      modify_response := {"set_headers": {"x-status-bucket": "5xx"}} if {
        input.response.status_code >= 500
      }
input merges what Lua's/JavaScript's two arguments (req/resp and ctx) carry into one document:
input key |
Present on | Meaning |
|---|---|---|
input.request.method, .path, .host, .headers |
request modifiers | same fields Lua's/JavaScript's req argument carries |
input.request.aipref.{train,search,ai_input} (also input.request.aipref["ai-input"]) |
both | mirrors ctx.request.aipref |
input.request.tls.* |
both | TLS fingerprint fields, mirrors ctx.request.tls |
input.principal.* |
both | mirrors ctx.principal, unchanged |
input.response.status_code, .headers |
response modifiers | same fields Lua's/JavaScript's resp argument carries |
The queried rule is a fixed name, data.sbproxy.modify_request / data.sbproxy.modify_response, the same way Lua and JavaScript modifiers call a fixed function name (modify_request / modify_response) with no config knob to rename it. Unlike policy: rego, a module that fails to parse does not refuse the config: the failure posture here matches the Lua/JS modifier row in §11, not the rego policy row above. There is also no data knob here: policy: rego's base-data table (above) has no modifier equivalent, matching Lua's and JavaScript's modifier forms, which have no analogous side-table either. See §7 for the full modifier field reference.
Testing Rego policies offline: sbproxy rego test
sbproxy rego test <path> is the offline opa test analogue: it runs one or more YAML fixture files against the module(s) they name and prints a per-module line-coverage summary, without touching sb.yml or a running proxy. <path> is either one fixture file or a directory, searched recursively for *_test.yaml / *_test.yml files (OPA's own *_test.rego naming convention, in sbproxy's YAML fixture shape).
Every fixture compiles its module through the same engine construction a live policy: rego or ai_routing_policy uses, so a fixture that passes here behaves identically pasted into config. A fixture's top-level fields mirror policies[] type: rego exactly and take the same defaults, so a block copied from a fixture into policies:, or the other way around, is the same policy:
| Field | Default | Meaning |
|---|---|---|
module |
- | Inline Rego source. Mutually exclusive with module_path |
module_path |
- | A .rego file. Resolved against the fixture file's own directory, not the CLI's working directory, so a fixture can colocate its module beside it regardless of where sbproxy rego test runs from |
query |
data.sbproxy.allow |
The rule reference every case in the file evaluates |
data |
none | Base data the module reads as data.<key> |
budget_ms |
50 |
Evaluation budget; must be greater than zero |
rego_v0 |
false |
Parse as pre-OPA-1.0 syntax |
cases |
required | A list of {name, input, expect}. expect is compared as JSON against the query's actual result; an undefined rule reads as null |
A real fixture, testing the module_path policy from examples/rego-modifier-parity:
# examples/rego-modifier-parity/policy_test.yaml
module_path: policy.rego
cases:
  - name: strong trust tier is allowed
    input:
      request: { trust_tier: strong, method: GET, path: /private/status }
    expect: true
  - name: public GET is allowed regardless of trust tier
    input:
      request: { trust_tier: anonymous, method: GET, path: /public/status }
    expect: true
  - name: private path with no strong trust tier is denied
    input:
      request: { trust_tier: anonymous, method: GET, path: /private/status }
    expect: false
  - name: POST to a public path is denied
    input:
      request: { trust_tier: anonymous, method: POST, path: /public/status }
    expect: false
PASS examples/rego-modifier-parity/policy_test.yaml :: strong trust tier is allowed
PASS examples/rego-modifier-parity/policy_test.yaml :: public GET is allowed regardless of trust tier
PASS examples/rego-modifier-parity/policy_test.yaml :: private path with no strong trust tier is denied
PASS examples/rego-modifier-parity/policy_test.yaml :: POST to a public path is denied
coverage: policy.rego 4/4 lines (100.0%)
4 passed, 0 failed, 0 errored, 100.0% total coverage
Exit code 0. A failing case exits 1 and names what it expected (FAIL <fixture> :: <case>: expected <value>, got <value>); --min-coverage <PCT> also exits 1 when aggregate coverage across every fixture in the run falls short. A fixture that is itself broken (unreadable, malformed YAML, a module/module_path conflict, no cases, a non-positive budget_ms) is recorded against that fixture and exits 2, without discarding the results of every other fixture in the same run. --format json emits one structured object (schema_version, cases, coverage, errors, ...) instead of the text lines above, for a CI step that parses the result rather than scrapes it. Fixture paths are trusted input: unlike a bundle manifest's entry, a fixture's module_path resolves against the fixture file's own directory with no path-traversal guard, so run sbproxy rego test only against fixtures you trust, including in CI.
4. Lua scripting
Lua gives you a full scripting language: variables, conditionals, helper functions, and string handling. The proxy uses the Luau runtime via mlua. Every invocation runs in a fresh sandboxed VM under a configurable wall-clock and memory budget; see §4.6 for the operator knobs.
4.1 Function contract
Lua modifier scripts define a named function; the proxy calls it with the request or response data plus a context table.
-- Request modifier: define modify_request(req, ctx), return a table.
function modify_request(req, ctx)
  return {
    set_headers = {
      ["X-Original-Path"] = req.path,
      ["X-Method"] = req.method
    }
  }
end
-- Response modifier: define modify_response(resp, ctx), return a table.
function modify_response(resp, ctx)
  if resp.status_code >= 500 then
    return { set_headers = { ["X-Upstream-Health"] = "degraded" } }
  end
  return { set_headers = { ["X-Upstream-Health"] = "ok" } }
end
On both paths, the only field the proxy applies from the returned table is set_headers: a map of header name to string value, inserted onto the upstream request or the client response. Lua modifiers cannot change the path, method, query, status, or body; use the typed modifier fields for those (section 7).
A legacy request script that defines match_request(req, ctx) and calls req:set_header(name, value) also works: the proxy falls back to it when modify_request is not defined.
4.2 Context tables
req (request modifiers)
req.method    -- "GET", "POST", ...
req.path      -- "/api/users"
req.headers   -- table, keys lowercase
req.host      -- the origin hostname that routed the request
req.tls.ja3   -- TLS fingerprints, empty strings on plain HTTP
req.tls.ja4
req.tls.ja4h
req.tls.trustworthy  -- boolean, false when no fingerprint was captured
Anything else you need (client IP, agent class) has to arrive as a header or be handled in CEL, where the wider namespace lives. Caller identity is on ctx.principal, below.
resp (response modifiers)
resp.status_code  -- numeric HTTP status
resp.headers      -- response headers table
ctx (second argument)
Request modifiers, response modifiers, and the Lua / JavaScript JSON transforms all receive the same context table. It carries the parsed aipref signal, the TLS fingerprint, and the unified caller identity:
ctx.request.aipref.train     -- boolean, default true
ctx.request.aipref.search    -- boolean, default true
ctx.request.aipref.ai_input  -- boolean, default true

ctx.request.tls.ja4          -- same fields as req.tls above

ctx.principal.tenant_id      -- tenant the request resolved to
ctx.principal.sub            -- subject id, "" for anonymous callers
ctx.principal.source         -- provider slug ("jwt", "virtual_key", ...)
ctx.principal.virtual_key.name
ctx.principal.virtual_key.allowed_providers  -- list
ctx.principal.attrs.project  -- attribution fields, "" when unset
ctx.principal.attrs.user
ctx.principal.attrs.team
ctx.principal.attrs.tags     -- list
ctx.principal.attrs.metadata -- map
ctx.principal.attrs.roles    -- list
ctx.principal.claims         -- verbatim JWT/OIDC claims map, {} otherwise
The principal shape is field-for-field the CEL principal.* namespace from section 3.1, so a policy written for CEL ports to Lua or JavaScript by swapping the dot paths. Empty and missing values render as empty strings, lists, and maps rather than being omitted, so a script can branch on ctx.principal.attrs.team without probing for presence first.
4.3 JSON helpers
Two global functions are registered in every Lua VM:
json_encode({name = "alice"})   -- '{"name":"alice"}'
json_decode('{"x":1}')          -- {x = 1}
-- json_decode raises an error on invalid input; wrap with pcall
-- when the input is untrusted.
local ok, t = pcall(json_decode, maybe_json)
These are the only host helpers. There is no logging, crypto, UUID, or time module in the Lua sandbox; if you need hashing, UUIDs, or timestamps, use CEL (sha256, uuid_v4, now) or do the work upstream.
4.4 Body transformation
Body transforms come in two shapes. type: lua runs transform(body, ctx) over the raw body string, so it works on any body, JSON or not. type: lua_json parses the body as JSON first and runs modify_json(data, ctx) over the parsed value; reach for it when the body is JSON and the script wants a parsed table instead of a string to json_decode itself.
origins:
  "api.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    transforms:
      - type: lua
        script: |
          function transform(body, ctx)
            return string.upper(body)
          end
      - type: lua_json
        script: |
          function modify_json(data, ctx)
            data.password = nil
            data.internal_id = nil
            data.processed = true
            return data
          end
Both accept a legacy format too: a script with no transform (or modify_json) function runs directly, with the body bound to a body global (the raw string for lua, the parsed value for lua_json), and the script's return value replaces the body.
4.5 Lua examples
Classify the caller from the User-Agent
origins:
  "api.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    request_modifiers:
      - lua_script: |
          function modify_request(req, ctx)
            local ua = req.headers["user-agent"] or ""
            local kind = "browser"
            if string.find(ua, "GPTBot") or string.find(ua, "ClaudeBot") then
              kind = "crawler"
            end
            return {
              set_headers = {
                ["X-Caller-Kind"] = kind,
                ["X-Original-Path"] = req.path
              }
            }
          end
Conditional header from a role header
request_modifiers:
  - lua_script: |
      function modify_request(req, ctx)
        local role = req.headers["x-role"] or ""
        local is_admin = "false"
        if role == "admin" then
          is_admin = "true"
        end
        return {
          set_headers = { ["X-Is-Admin"] = is_admin }
        }
      end
Tag responses by upstream status
response_modifiers:
  - lua_script: |
      function modify_response(resp, ctx)
        local bucket = "2xx"
        if resp.status_code >= 500 then
          bucket = "5xx"
        elseif resp.status_code >= 400 then
          bucket = "4xx"
        end
        return {
          set_headers = {
            ["X-Status-Bucket"] = bucket,
            ["X-Content-Type-Options"] = "nosniff"
          }
        }
      end
Stamp the aipref verdict onto the response
response_modifiers:
  - lua_script: |
      function modify_response(resp, ctx)
        local train = "yes"
        if ctx.request.aipref.train == false then
          train = "no"
        end
        return {
          set_headers = { ["X-AIPref-Train"] = train }
        }
      end
Compute a JSON field from two others
transforms:
  - type: lua_json
    script: |
      function modify_json(data, ctx)
        if data.first_name and data.last_name then
          data.full_name = data.first_name .. " " .. data.last_name
        end
        data.is_adult = (data.age or 0) >= 18
        return data
      end
For path rewriting, method overrides, query-string edits, and body replacement, use the typed modifier fields alongside (or instead of) a script; see section 7.
4.6 Sandbox limits
Every Lua invocation runs under a configurable sandbox. The defaults are tight enough to keep an adversarial script from stalling a worker; raise them if your scripts legitimately need more headroom, or tighten them further on sensitive deployments.
proxy:
  scripting:
    lua:
      sandbox:
        max_execution_ms: 100   # wall-clock budget per invocation
        max_memory_mb: 8        # cap on the Lua VM's allocator footprint
        allow_patterns: true    # expose string.find / match / gmatch / gsub
| Field | Default | Notes |
|---|---|---|
max_execution_ms |
100 |
Wall-clock budget per invocation. Scripts that exceed it abort with a sandbox-timeout error and the request fails closed. Set 0 to disable the timer (not recommended). |
max_memory_mb |
8 |
Hard ceiling on the Lua VM's allocator footprint. Allocations past the cap fail the script rather than letting it grow the proxy's resident set. |
allow_patterns |
true |
Whether to expose the Lua pattern API (string.find, string.match, string.gmatch, string.gsub). Those four are every function in the string table that takes a pattern. The pattern engine has known pathological inputs, and max_execution_ms cannot stop one: the matcher runs inside the C string library, where the interrupt the timer relies on never fires. Flip to false if your scripts do not need pattern matching. The rest of string.* keeps working either way. |
Limits apply to every Lua surface uniformly: request modifiers, response modifiers, JSON transforms, and WAF custom rules. Changes take effect on the next config reload (SIGHUP, admin reload, or filesystem watch) without restarting the process.
5. JavaScript scripting
JavaScript runs on QuickJS via rquickjs. Every invocation gets a sandboxed engine with eval removed and two global helpers registered: json_encode (alias of JSON.stringify) and json_decode (alias of JSON.parse). There is no atob, btoa, Buffer, TextEncoder, or crypto; a script that needs those carries its own.
Response modifiers define modify_response(resp, ctx) and, like Lua, only the returned set_headers map is applied:
response_modifiers:
  - js_script: |
      function modify_response(resp, ctx) {
        return {
          set_headers: {
            "X-Processed-By": "js",
            "X-Status": String(resp.status_code)
          }
        };
      }
Body transforms come in two shapes. type: javascript runs transform(body, ctx) over the raw body string (a non-string return value is JSON-serialized); type: js_json runs modify_json(data, ctx) over the parsed JSON body. Both accept an optional function_name to call a differently named entrypoint.
transforms:
  - type: javascript
    script: |
      function transform(body, ctx) {
        return body.toUpperCase();
      }
  - type: js_json
    script: |
      function modify_json(data, ctx) {
        data.processed = true;
        return data;
      }
The ctx argument carries the same context table as the Lua surfaces in section 4.2: ctx.request.aipref.* (each flag defaulting to true when the request has no valid aipref header), ctx.request.tls.* (JA3/JA4/JA4H fingerprints, empty strings on plain HTTP), and ctx.principal.* (the unified caller identity, mirroring the CEL principal.* namespace from section 3.1).
5.1 Sandbox limits
QuickJS always runs with a sandbox. The defaults keep an adversarial script from stalling a worker; raise them if your scripts legitimately need more headroom, or tighten them on sensitive deployments.
proxy:
  scripting:
    javascript:
      sandbox:
        budget_ms: 100    # wall-clock CPU budget per invocation
        memory_mb: 16     # heap cap for the QuickJS runtime
        stack_kb: 1024    # native stack cap
| Field | Default | Notes |
|---|---|---|
budget_ms |
100 |
Wall-clock CPU budget per invocation. A script that overruns it is aborted by a watchdog with an uncatchable exception; the modifier or transform is skipped and the error is logged. This is the guard against while (true) {}. |
memory_mb |
16 |
Heap cap for the QuickJS runtime. An allocation past the cap fails the script rather than letting it grow the proxy's resident set. |
stack_kb |
1024 |
Native stack cap. Guards against deeply recursive scripts. |
Limits apply to every JavaScript surface uniformly: response modifiers, body
and JSON transforms, WAF custom rules, MCP adapters, and engine: js custom
log fields. Changes take effect on the next config reload (SIGHUP, admin
reload, or filesystem watch) without restarting the process, the same as the
Lua block in §4.6.
6. WASM scripting
WASM modules run in wasmtime against the WASI preview-1 ABI. The host pipes the response body in on the module's stdin and captures whatever the module writes to stdout. There is no custom calling convention to learn; any wasm32-wasi binary that reads stdin and writes stdout works.
WASM is currently exposed as a body transform (type: wasm), not as a request/response modifier. Use it when you need to mutate the response body in a language that does not have a first-class engine here (Rust, TinyGo, AssemblyScript, Zig, etc.) or when you want stronger isolation than CEL or Lua provide.
Because the contract is raw bytes on stdin, a WASM module does not receive the ctx context the Lua and JavaScript surfaces get by default: there is no JSON envelope to carry principal or request.tls, and putting one on stdin would break every deployed module that parses its body off stdin unmodified. If a module needs caller identity or fingerprint data, three options exist, in order of preference: gate the transform with a CEL policy, stamp the needed value into a header with a Lua/JS modifier ahead of it, or set request_context: true (below) if the module itself needs to branch on it.
origins:
  "wasm.local":
    action:
      type: static
      status_code: 200
      content_type: text/plain
      body: "hello from sbproxy"
    transforms:
      - type: wasm
        module_path: /etc/sbproxy/modules/uppercase.wasm
        timeout_ms: 500
        max_memory_pages: 256
Sandbox tunables:
| Field | Default | Description |
|---|---|---|
module_path |
required | Filesystem path to a .wasm module compiled for wasm32-wasi. Resolved relative to the proxy's working directory. |
module_bytes |
optional | Inline bytes of a precompiled module. One of module_path or module_bytes must be set. |
sha256 |
optional | Lowercase hex SHA-256 digest the selected module bytes must match; a mismatch is refused before compilation. |
timeout_ms |
1000 | Hard wall-clock cap per invocation. Enforced via wasmtime's epoch interruption. |
max_memory_pages |
256 | Linear-memory cap in 64 KiB pages. 256 = 16 MiB. |
max_fuel |
1,000,000,000 | Deterministic, instruction-granular cap on one invocation, complementing timeout_ms. |
request_context |
false |
Opt-in per-request ctx, described below. Costs the transform its response-cache eligibility. |
There is no filesystem access, no network access, and no clock skew the host can observe. There are no environment variables either, with one narrow, opt-in exception described in 6.1: request_context: true.
There is also no allowed_hosts:. The key used to be accepted here and was never enforced, which is the wrong shape for something that reads as a security boundary: modules get no sockets at all, so an allowlist had nothing to sit in front of. It is refused at config compile now, with an error saying so. If a host callout ever lands, the key comes back as an enforced one. Until then, keep the reaching on the proxy side: gate the origin with an expression policy, or route the callout through an origin the proxy controls.
The full authoring guide is in wasm-development.md, with hello-world Rust and TinyGo modules in examples/wasm/.
6.1 request_context: opting a module into ctx
Setting request_context: true on a wasm transform hands its module the same ctx JSON document (principal, request.aipref, request.tls) that Lua and JavaScript body transforms get, described in 4.2. Nothing changes about stdin: the response body still arrives there, byte for byte, exactly as it does today. The context rides a separate channel instead, a WASI environment variable named SBPROXY_REQUEST_CONTEXT holding the JSON document as a string. A module reads it the way it would read any other environment variable in its language (std::env::var in Rust, os.Getenv in TinyGo).
transforms:
  - type: wasm
    module_path: /etc/sbproxy/modules/redact-by-role.wasm
    request_context: true
This is deliberately opt-in and off by default, for two reasons. First, cheapest: a module that has never heard of SBPROXY_REQUEST_CONTEXT keeps compiling and running unmodified; nothing about its stdin bytes or observable behavior changes. Second, and the one to plan around: request_context: true makes the transform request-dependent, the same as lua_json, javascript, and js_json already are, and the config compiler refuses to combine a request-dependent transform with response_cache on the same origin, because a per-requester ctx baked into a shared cache entry would leak one caller's context to every other caller. Leave request_context unset (or false) to keep a wasm transform eligible for response_cache; the flag is a trade an operator makes deliberately, per transform, not a default cost every module pays.
Cache decision events
response_cache is otherwise static. Two optional events let a script answer part of it per request: key_event decides what the cache key varies on, and admit_event decides whether a finished response is stored and for how long. Both sit under an origin's response_cache block and both accept lua and js, in the same source plus engine shape as custom_fields.
They are two events rather than one cache policy because of an ordering constraint. A key has to exist before anything can be looked up under it, so key_event runs on the request, before the lookup, with no response in scope. Whether a response is worth storing depends on its status and its size, neither of which exists at request time, so admit_event runs after the response body is complete.
CEL is not on the list, and the reason is the return type. Every CEL surface in section 2 answers with one scalar: a bool, a bucket key, a header value. These events answer with a document, so serving them from CEL would mean packing a document into a string and parsing it back out, which is how route_to:gpt-4o-mini became a mini-language. engine: cel is refused at config compile, naming lua and js instead. engine: wasm is refused on different grounds: the field takes inline source and a compiled module is not inline source, so a WASM hook attaches through an extension bundle.
origins:
  "api.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
    response_cache:
      enabled: true
      ttl_secs: 300
      cacheable_status: [200]
      key_event:
        engine: lua
        source: |
          -- Reports are per tenant and per plan tier. Everything else
          -- keeps the origin's static `vary:`.
          if string.find(ctx.request.path, "/v1/reports", 1, true) == 1 then
            return {
              vary = { "header:x-plan-tier", "header:x-region" },
              reason = "a report body differs per tenant and per plan tier",
            }
          end
          return {}
      admit_event:
        engine: js
        source: |
          (() => {
            if (ctx.response.body_bytes > 1048576) {
              return { store: false, reason: "too large to be worth a cache slot" };
            }
            if (ctx.response.headers["cache-control"] === "no-store") {
              return { store: false, reason: "upstream said no-store" };
            }
            return { store: true, ttl_secs: 60, reason: "report bodies go stale fast" };
          })()
What the script receives
Each event hands its input to the script as a ctx global, the same way engine: lua and engine: js custom log fields do. This is not the modifier context table from section 4.2: there is no principal, no aipref, and no TLS fingerprint here.
key_event sees the request:
ctx.request.method
ctx.request.path
ctx.request.query    -- "" when the request carries none
ctx.request.host
ctx.tenant           -- resolved tenant id, "" when there is none
ctx.origin           -- origin id
admit_event sees the finished response, plus enough of the request to tell one route from another:
ctx.response.status
ctx.response.body_bytes
ctx.response.headers  -- names lowercased; hop-by-hop headers dropped
ctx.request.path
ctx.request.host
ctx.tenant
ctx.origin
Request headers are deliberately not in either context. A key_event names the dimensions and the host resolves their values, so a script can vary on a header it cannot read. To branch on a header value, stamp a derived value into the path or route the traffic to its own origin.
What the script returns
Lua returns the document (return { ... }); JavaScript evaluates to it, so wrap anything with branches in an immediately invoked function as above. A bare object literal at the end of a JavaScript source is parsed as a block, not an object.
key_event:
| Field | Type | Meaning |
|---|---|---|
vary |
list of strings | Dimensions folded into the cache key, added to the origin's static vary:. At most 16, each at most 128 bytes. |
skip_lookup |
bool | Go upstream for this request rather than reading the cache. The response stays eligible for storage. |
reason |
string | Free text explaining the plan, trimmed and truncated at 512 bytes. Carried with the decision; nothing branches on it. |
admit_event:
| Field | Type | Meaning |
|---|---|---|
store |
bool | Required. Whether this response is written to the cache. |
ttl_secs |
int | TTL for this entry, replacing the configured ttl_secs. Clamped to 30 days. |
reason |
string | Same free text, same bounds. |
Declining is the cheap common case and means "the static config applies unchanged": return {} or return nil in Lua, an empty object or nothing at all in JavaScript. A key_event document with no vary and no skip_lookup declines too. admit_event is the one exception to everything being optional: any document that is not empty has to carry store, because there is no safe default for it. Guessing true caches a response the policy never approved, and guessing false switches the cache off without saying so.
Rules the events cannot bend
Dimension names are a closed set. Each name in vary is either query or a request header written header:<name>. Anything else is refused when the document is decoded. A name resolving to nothing would contribute the same empty value to every request, partition nothing, and merge every caller into one cache entry, so a typo has to fail loudly rather than quietly serve one customer's response to another. Names are trimmed, lowercased, deduplicated, and sorted, which keeps the same set in a different order producing the same key.
A key can only get narrower. Every field of v2:<workspace>:<tenant>:<hostname>:<method>:<path>:<identity>:<query>: is stamped by the host whatever the event returns, and the event reaches only the Vary fingerprint that follows them, so a policy adds dimensions and can never widen a key. Worth being precise about what separates tenants and callers: workspace is empty on every path today, so tenant separation comes from tenant and hostname plus the per-origin cache store, and caller separation from identity, a digest of the credentials the request presented. None of the three is addressable from a policy.
A faulted key_event bypasses the cache. If the engine faults, or the document cannot be decoded, the request gets no cache read and no cache write. Falling back to the static vary: alone would produce a coarser key rather than a narrower one, and the same key carries the write-back, so that response would be published to every other caller whose script also faulted. admit_event fails the other way, because nothing about the key changed: a fault there stores the response under the configured ttl_secs, which is what an origin without the event already does.
skip_lookup is not a refusal to cache. It sends this request upstream and leaves the response eligible for storage, which is what a caller asking for fresh data usually wants. To keep a response out of the cache, return store: false from admit_event.
admit_event runs downstream of cacheable_status. It only sees a response whose status already passed that gate, so it can decline a status the gate allows and cannot start caching one the gate excludes.
admit_event and stale_while_revalidate compose. The revalidation refresh runs the event against the response it just fetched, from the same small request-side scope the initial request used, so an override or a refusal from admit_event still applies to what the background refresh writes back. The two were refused together before this evaluation path existed; that restriction is gone.
Neither event normally runs on the connection loop. Both are evaluated on a separate worker pool, so a script that spends its whole CPU budget (max_execution_ms, 100 ms by default) occupies a pool thread instead of the worker that owns the connection, and the other connections that worker is serving keep moving.
Three consequences worth knowing.
- An origin with neither event is unchanged, because the scheduling hop is only paid when a script exists to run.
- For an origin with an
admit_event, the cache write-back is dispatched one hop later than before.admit_eventdecides whether a response is stored, never whether it is served, so nothing the client is waiting for moves with it. - The
admit_eventdeferral is capped at 64 evaluations in flight across the whole process, because each one holds a copy of the response body until the script returns and nothing downstream is waiting to push back. Past the cap the event runs on the connection loop after all, which is slower but bounded, and which keeps a refusal from being skipped under load. A script expensive enough to reach that cap shows up onsbproxy_decision_event_duration_seconds{event="cache.admit"}before it gets there.
Both events run under the sandboxes in §4.6 and §5.1, with a fresh VM per evaluation. Evaluations are counted on sbproxy_decision_event_total{event="cache.key"} and {event="cache.admit"}, and the two faults are counted differently on purpose: cache.admit fails open, so it records outcome="allow" plus sbproxy_decision_event_fail_open_total, while cache.key fails closed on the cache and records outcome="error", or outcome="timeout" when the script ran out of its CPU budget, with no fail-open counter. The field-level reference for the block is in configuration.md.
7. Modifier reference
Request and response modifiers are lists of typed entries. Each entry can combine the structural fields below with an optional script; entries apply in order.
Request modifier fields
| Field | Type | Description |
|---|---|---|
headers.set |
map | Set headers, replacing existing values |
headers.add |
map | Append headers, preserving existing values |
headers.remove |
list | Remove headers by name (alias: delete) |
url.path.replace |
map | { old, new } substring replacement on the path |
query.set |
map | Set (overwrite) query parameters |
query.add |
map | Add query parameters, appending even when the key exists |
query.remove |
list | Remove query parameters by name (alias: delete) |
method |
string | Override the HTTP method (e.g. "POST") |
body.replace |
string | Replace the request body with this string |
body.replace_json |
any | Replace the request body with this JSON value |
lua_script |
string | Lua modify_request(req, ctx); returned set_headers applied |
js_script |
string | JavaScript modify_request(req, ctx); returned set_headers applied |
rego_module / rego_module_path |
string | Rego data.sbproxy.modify_request; returned {"set_headers": {...}} applied. Mutually exclusive with each other |
rego_budget_ms |
int | Rego evaluation budget in milliseconds. Defaults to 50. Must be greater than zero |
rego_v0 |
bool | Parse the Rego module as pre-OPA-1.0 syntax |
request_modifiers:
  - headers:
      set:
        X-Forwarded-Env: production
      remove:
        - X-Internal-Debug
    url:
      path:
        replace:
          old: /v1/
          new: /v2/
    query:
      add:
        source: proxy
      remove:
        - debug
    method: POST
Response modifier fields
| Field | Type | Description |
|---|---|---|
headers.set / headers.add / headers.remove |
map / map / list | Same semantics as the request side |
status.code |
int | Override the response status code |
status.text |
string | Custom reason phrase for the HTTP/1.x status line; ignored on HTTP/2, which has no reason phrase on the wire |
body.replace |
string | Replace the response body with this string |
body.replace_json |
any | Replace the response body with this JSON value |
lua_script |
string | Lua modify_response(resp, ctx); returned set_headers applied |
js_script |
string | JavaScript modify_response(resp, ctx); returned set_headers applied |
rego_module / rego_module_path |
string | Rego data.sbproxy.modify_response; returned {"set_headers": {...}} applied. Mutually exclusive with each other |
rego_budget_ms |
int | Rego evaluation budget in milliseconds. Defaults to 50. Must be greater than zero |
rego_v0 |
bool | Parse the Rego module as pre-OPA-1.0 syntax |
response_modifiers:
  - headers:
      set:
        X-Frame-Options: DENY
        Strict-Transport-Security: max-age=31536000
      remove:
        - X-Powered-By
        - Server
    status:
      code: 503
    body:
      replace_json:
        error: "Service temporarily unavailable"
For JSON body surgery on responses, prefer the JSON transforms: the typed json transform (set / remove / rename fields) for static edits, or lua_json / js_json for computed edits.
When one modifier entry declares more than one script form together, they all run, in the fixed order lua_script, then js_script, then rego_module / rego_module_path, and the later engine wins when more than one sets the same header name.
8. AI-gateway scripting pointers
The AI proxy action does not embed the general scripting engines. It has two dedicated surfaces:
ai_policy: a single sandboxed CEL expression over theai.*namespace (surface, model, provider, principal tier, guardrail verdicts, budget state, token estimates) that returns typed action tokens (allow,block,redact,route_to:<model>,set_sink_tag:<tag>,audit:<priority>). See ai-policy-cel.md and examples/ai-policy-cel/.- Guardrails: typed
guardrails: input:/output:blocks (injection,pii,jailbreak,toxicity,schema, ...), configured declaratively rather than as expressions. See ai-gateway.md and examples/ai-guardrails/.
9. Sandbox limits summary
CEL
- Non-Turing-complete: no loops, no side effects, no I/O.
- No access to secrets. Evaluation typically completes in microseconds.
- User-supplied regex patterns (
regex_match) are capped at 1024 bytes and a bounded compile size; oversized or invalid patterns evaluate false. - Deliberately has no wall-clock budget, fuel, or memory cap at evaluation time, and no
proxy.scripting.celblock to set one. The language terminates by construction (no loops, no recursion), so the only unbounded work a CEL expression can request is regex compilation, and that is what the two regex caps bound. Theceltransform logs when one header rule takes longer than a millisecond, but that budget is advisory: it is measured after the evaluation, and cannot preempt one.
Rego
The four bullets below describe policies[] type: rego and ai_routing_policy engine: rego, the two surfaces §3a documents in full. The Rego modifiers and runtime: rego bundle surfaces share the same Regorus engine and the same budget mechanism, but not this section's compile-time or failure-posture claims; see the fifth bullet.
- One evaluation runs under
budget_ms(default 50 ms, matching the extension-bundle sandbox default), enforced by the Regorus execution timer, which checks the deadline every thousand work units.budget_ms: 0is refused at config load. - Deliberately has no memory or stack cap and no fuel: the execution timer bounds total work, and a policy is one bounded evaluation over an already-bounded input document rather than a body-sized stream.
- Configured per policy (
policies[] type: rego, fieldbudget_ms), not underproxy.scripting. Modules are compiled and semantically checked at config load, including one trial evaluation, so authoring mistakes cannot defer to request time. A trial that only exceedsbudget_msis inconclusive: compile proceeds, and the request path still denies when the same budget is exceeded for real. - Every fault denies the request; there is no
failure_postureknob on this surface. See §3a. - A request/response modifier's
rego_modulecompiles fresh per invocation instead, under its ownrego_budget_ms(same 50 ms default), and a fault is logged and the modifier skipped rather than denying, matching the Lua/JS modifier posture. A signed extension bundle'sruntime: regopolicy hook compiles once at candidate load likepolicies[] type: rego, but a request-time fault propagates to the bundle manifest'sfailure_posture(openadmits,closedrefuses) instead of always denying, the same fault path every other bundle policy hook shares.
Lua
- Fresh VM per invocation: globals never leak between calls.
- Nil'd out:
os,io,loadfile,dofile,require,rawset,rawget,load,loadstring,debug,package. - No network operations.
- Wall-clock budget (default 100 ms) enforced via the Luau interrupt callback; memory cap (default 8 MB) enforced by the allocator.
- Deliberately has no instruction metering: the interrupt callback bounds an infinite loop by wall clock, so counting instructions would duplicate a bound that already holds. Setting
max_execution_ms: 0disables the timer and is not recommended. - Available standard library:
string.*(the pattern functionsfind,match,gmatch, andgsubgated byallow_patterns),table.*,math.*,tonumber,tostring,type,pairs,ipairs,select,pcall,error.
JavaScript
- Fresh sandboxed engine per invocation;
evalremoved. - CPU budget (default 100 ms) enforced via a watchdog interrupt; heap cap (default 16 MB) and native stack cap (default 1 MB) enforced by the runtime. All three are tunable under
proxy.scripting.javascript.sandboxand reload without a restart. - No filesystem, no network, no module loader.
WASM
- Wasmtime sandbox running WASI preview-1. No network, no filesystem, no environment variables, no host clock beyond the epoch-interruption deadline.
- Per-request
Storeso module state never leaks between requests; the compiledModuleis shared across calls so per-invocation cost is one instantiate plus one_start. timeout_msis enforced via epoch interruption;max_memory_pagescaps linear memory.- There is no host allowlist because there is nothing to allow: modules get no sockets. An authored
allowed_hosts:is refused at config compile rather than accepted as a boundary nothing checks.
Capability matrix
One row per engine; every empty cell is a decision, not an omission, and the notes above say why. Extension bundles appear as their own row because their limits come from the bundle manifest rather than from sb.yml.
| Engine | Wall clock | Memory | Stack | Fuel | Output cap | Limits configured in |
|---|---|---|---|---|---|---|
| CEL | none (terminates by construction; regex caps only) | none | none | none | none | nowhere: the regex caps are fixed |
| Rego | budget_ms (policy/routing) or rego_budget_ms (modifiers), default 50 ms either way |
none | none | none | none | per policy (budget_ms) or per modifier (rego_budget_ms) |
| Lua | 100 ms interrupt | 8 MB allocator | none | none (wall clock covers it) | none | proxy.scripting.lua.sandbox |
| JavaScript (inline) | 100 ms watchdog | 16 MB heap | 1 MB native | none (wall clock covers it) | none | proxy.scripting.javascript.sandbox |
WASM (transform: wasm) |
timeout_ms, default 1 s, epoch interruption |
max_memory_pages, default 256 pages (16 MiB) |
module-internal | max_fuel, default 10^9 |
none | the transform's own config block |
| Bundle hooks (JS / envelope WASM) | budget_ms, default 50 ms, max 1 s |
memory_mb, default 16 MB, max 64 MB |
stack_kb, default 512 KB, max 2 MB |
max_fuel (WASM only), default 10^8 |
max_output_bytes, default 1 MiB, max 16 MiB; input capped by max_buffer_bytes |
the bundle manifest's sandbox: block |
Two absences worth naming across the whole table. No inline engine caps its output size; the surfaces they attach to bound the result instead (a header value, a JSON body already capped by max_body_size, a log field). And no engine gets network, filesystem, or clock access anywhere in this table; the only I/O an extension can request is the declared, host-mediated kind documented in extension-bundles.md.
Where each engine attaches is section 2's table; what each surface hands the script is §3.2 for CEL and the per-engine sections above for the rest; what happens when a script fails is the error table in §11.
10. Performance notes
CEL evaluates in microseconds per request and fits any routing decision, including high-frequency hot paths. Prefer CEL over Lua, JavaScript, or WASM when the logic fits.
Lua and JavaScript build a fresh interpreter state per invocation. That is the isolation guarantee, and it means simple scripts complete in well under a millisecond but there is no cross-request state to amortize into.
WASM has a one-time compilation cost at config load; subsequent invocations run at near-native speed inside the Wasmtime sandbox, paying one instantiation per request. policies[] type: rego, ai_routing_policy, and a bundle's runtime: rego policy hook share that one-time cost: each compiles and trial-evaluates its module once, at config load or candidate load. A request/response modifier's rego_module does not: it compiles fresh (parse plus one trial evaluation) on every invocation, so a broken module stamps a record_script_compile failure on every request that reaches it rather than once at load, the trade-off for rego_module/rego_module_path living in a list evaluated per request rather than a config-load-time slot.
Tips:
- Prefer
startsWith,endsWith, orcontainsoverregex_matchin CEL hot paths. - In Lua, use
localvariables. Local variable access is faster than global lookup. - In Lua, prefer
table.concat()over string concatenation in loops. - Keep scripts under ~30 lines. If you need more, consider whether a typed modifier, transform, or policy fits better.
- Expressions that always return the same result regardless of request data should be replaced with static config values.
11. Debugging scripts
Config validation
Validate your config before deployment:
sbproxy validate sb.yml
Validation checks the YAML shape and typed fields, and compiles every CEL expression the config declares: expression and assertion policies, rate-limit and WAF persistent-block key: expressions, cel transform bodies and header rules, and engine: cel custom log fields. A CEL syntax error in any of them surfaces here, and at boot and reload, rather than at request time. Inline Lua and JavaScript bodies are still strings to the validator, so their syntax errors surface at request time in the logs. The response_cache decision events are checked as far as they can be without running: an engine other than lua or js, or an empty source, is refused here and at boot and reload, while the script body stays a string until it runs. Dynamic bundle JavaScript and TypeScript are different: the candidate loader parses the entry, transpiles TypeScript when needed, verifies every named export, and refuses the candidate before publication when any of those steps fails.
Enabling debug logging
sbproxy --log-level debug -f sb.yml
With debug logging on, script failures are logged with the engine, the error message, and (for Lua and JavaScript) the failing function. Script health is also visible in metrics: sbproxy_script_compile_total{engine, result}, sbproxy_script_invocations_total{engine, result}, and sbproxy_script_duration_seconds{engine}.
Error behavior
| Surface | On error |
|---|---|
expression policy |
A CEL parse error rejects the config at compile time (boot refuses to start; a reload keeps the previous config active); an evaluation error fails closed and denies the request (the expression could not prove the request is allowed) |
assertion policy |
A CEL parse error rejects the config at compile time; an evaluation error is logged and recorded as a pass (the policy is log-only and gates nothing) |
rate-limit key: |
A CEL parse error rejects the config at compile time; an empty or null result falls back to the default client key; an evaluation error buckets the request under the __cel_key_error__: namespace and logs |
WAF persistent_block.key |
A CEL parse error, or track_by: cel with no key:, rejects the config at compile time; an evaluation error leaves the request untracked (no strike, no block) |
engine: cel custom log field |
A CEL parse error rejects the config at compile time; an evaluation error is logged at debug and the field is omitted from the line |
rego policy |
A module that fails to parse or a semantic fault (unsafe variable, query naming no rule) rejects the config at compile time; a load-time trial that only exceeds budget_ms is inconclusive and does not refuse compile; a rule error, non-boolean result, or exceeded budget_ms at request time denies the request with deny_status |
forward-rule when: |
A CEL parse error rejects the config at compile time; an evaluation error means the rule does not match, logged per request |
| WAF custom rule (Lua / JS) | A rule whose script errors is skipped and counted; if no rule blocked but at least one went unevaluated, the pass reports a WAF failure and the policy's failure_posture decides (default closed) |
| Lua / JS / Rego modifiers | Error logged per request; the modifier's headers are not applied; the request proceeds. Unlike policy: rego, a Rego modifier module that fails to parse follows this row, not the rego policy row above: the module is not compiled at config load |
lua_json / js_json / javascript transforms |
Error logged per request; the body is left unchanged |
cel transform |
A missing or empty headers: array, a CEL parse error in any value_expr, a header rule reaching for a binding no route on its origin can supply (response.body where every route streams, response.headers where every route buffers, any rule at all on an action that runs no transform chain), an authored on_request: (removed; transforms have no request phase), or an authored on_response: / expression: (removed; CEL decides rather than produces) fails config compile; a rule the config accepted but this route's phase cannot bind is skipped, counted on sbproxy_errors_total, and logged; a runtime evaluation error skips only the failing header rule |
| WASM transform | Missing module_path / module_bytes, a module that fails to compile, or an authored allowed_hosts: (removed; modules have no network surface) fails config compile; runtime errors skip the transform |
response_cache.key_event |
An engine of cel or wasm, any other unknown engine, or an empty source fails config compile; an engine fault or a document that cannot be decoded is logged and bypasses the cache for that request, with no read and no write |
response_cache.admit_event |
The same config-compile checks; composes with stale_while_revalidate (the background refresh runs the event too). An engine fault or a document that cannot be decoded is logged and the response is stored under the configured ttl_secs |
| JavaScript / TypeScript bundle hook | Invalid source, imports, a missing export, an invalid return envelope, timeout, or resource-limit error follows the bundle's failure_posture; candidate-load failures reject the whole candidate. |
| Envelope WASM bundle hook | Invalid ABI, compile failure, malformed output, timeout, or resource-limit error follows failure_posture; candidate-load failures reject the whole candidate |
| Proxy-Wasm filter | An unsupported import, invalid ABI, trap, resource-limit error, or unresolved Pause becomes a bounded filter failure and follows the resolved failure_posture |
Common mistakes
CEL header key case. Headers are normalized to lowercase. Use request.headers["content-type"], not request.headers["Content-Type"].
CEL missing keys. Accessing a missing key can surface as an evaluation error, and the expression policy fails closed on evaluation errors. Guard with size(...) checks (e.g. size(jwt.claims) > 0) before indexing into maps that may be empty.
Lua array indexing is 1-based. arr[1] is the first element. #arr is the length.
Lua inequality operator. Lua uses ~= for not-equal, not !=.
Lua modifiers only set headers. Returning path, status_code, or body from modify_request / modify_response does nothing; those belong to the typed modifier fields (section 7).
AI policy CEL is a different namespace. The ai_policy expression sees ai.* variables, not request.*; see ai-policy-cel.md.
12. Dynamic extension bundles
For packaging and distributing JavaScript, TypeScript, and WASM behaviors as reusable components, SBproxy supports Extension Bundles.
For full details on the extension architecture, candidate loading, and manifest reference, see the dedicated Extension bundles guide.
Examples in Practice
To see custom scripting and transforms in action, refer to these runnable examples:
| Example | What it is | How to use it | Outcome |
|---|---|---|---|
transform-javascript |
Payload rewriting via JavaScript. | Use type: javascript in your transforms: block. |
Sandboxed QuickJS execution for JSON body edits. |
transform-json |
Fast structural JSON edits. | Use type: json with rename / remove / set steps. |
Cleanly add, remove, or rename JSON fields without a full JS runtime. |
transform-json-schema |
Response JSON validation. | Apply a type: json_schema transform. |
Rejects a malformed upstream response with a synthetic 502 before it reaches the client. |
transform-markdown |
Markdown to HTML conversion. | Use type: markdown. |
Renders a Markdown response body as HTML via pulldown-cmark. |
transform-template |
Dynamic payload rendering. | Use the template transform with minijinja (Jinja-style) syntax. |
Renders a structured JSON body into a plain-text (or other) summary. |
variables-template |
Origin variable and env var interpolation. | Reference {{ variables.<name> }} / {{ env.<NAME> }} in modifier fields. |
Injects config-defined values into headers sent upstream, resolved once when the config compiles (not per request). |
rego-modifier-parity |
A file-based Rego policy plus a Rego response modifier. | Use policies[] type: rego with module_path, and response_modifiers[].rego_module. |
A strong trust tier or a public GET is allowed; everything else is denied 403. Test the module offline first with sbproxy rego test. |
See also
- configuration.md - general configuration model and the full
sb.ymlfield reference. - features.md - higher-level feature overview.
- ai-gateway.md - AI gateway routing and guardrails.
- ai-policy-cel.md - the unified CEL policy plane for the AI gateway.
- examples/extension-bundles - runnable JavaScript, TypeScript, envelope WASM, Proxy-Wasm, AI, and payment bundle examples.