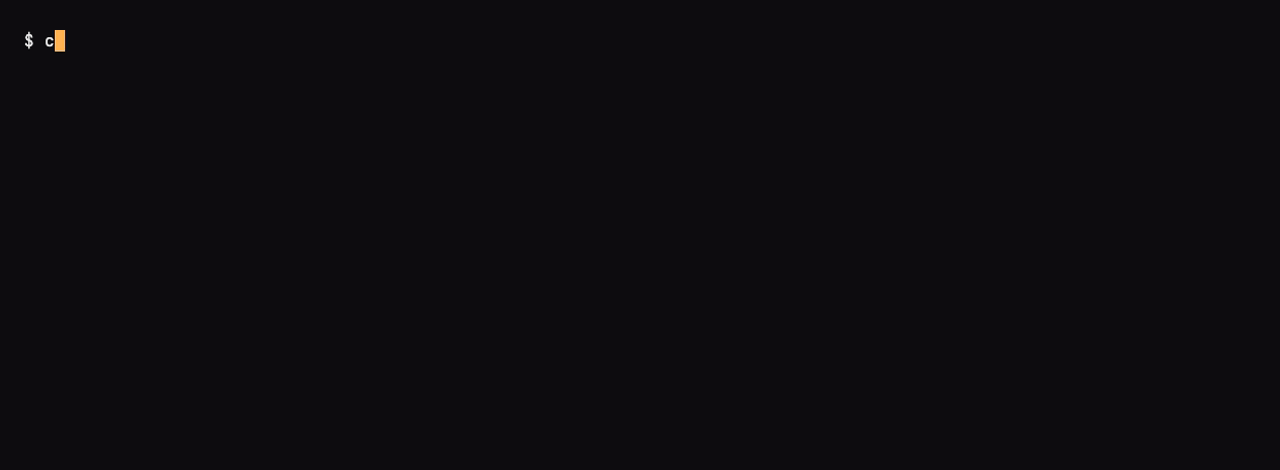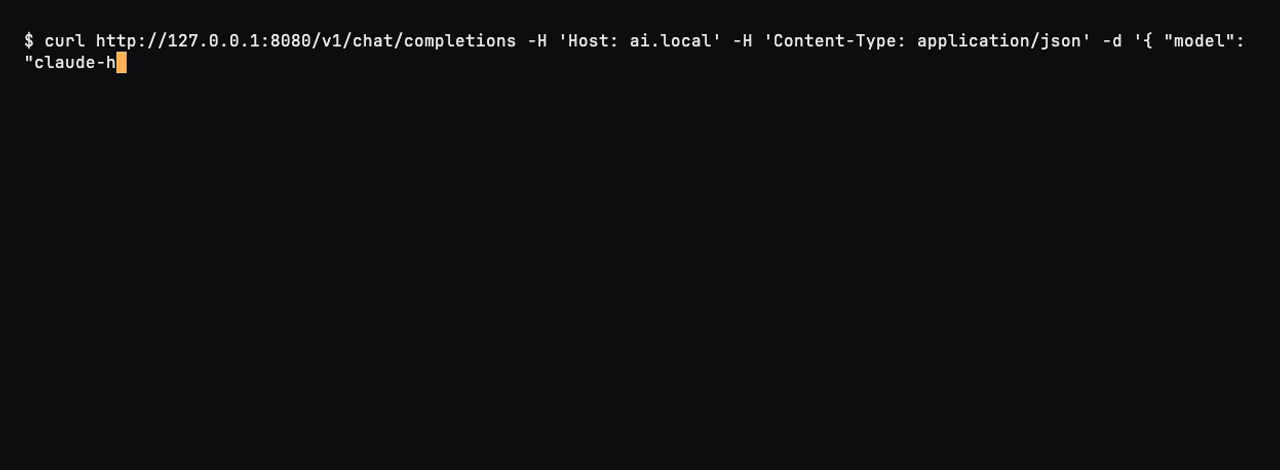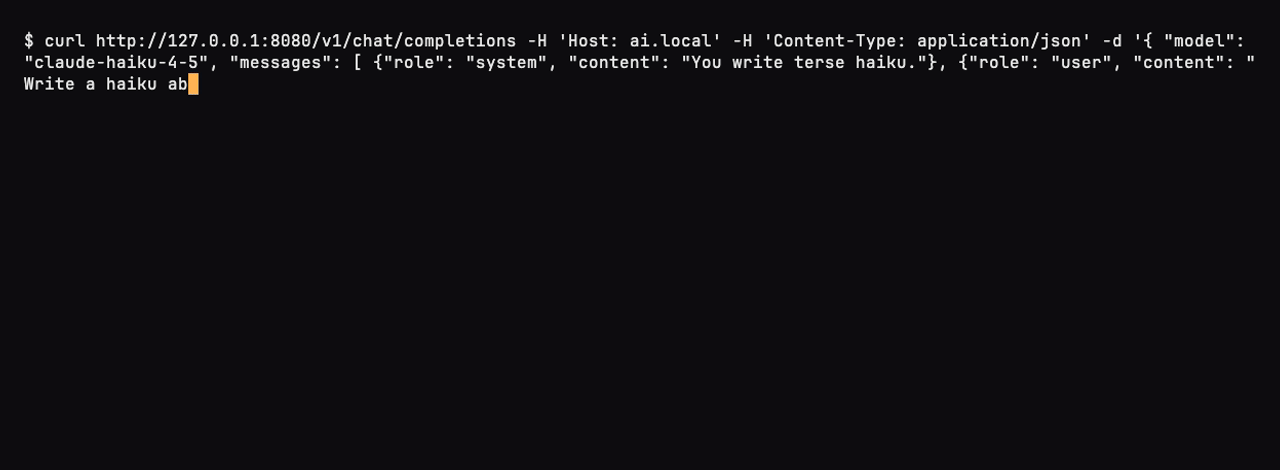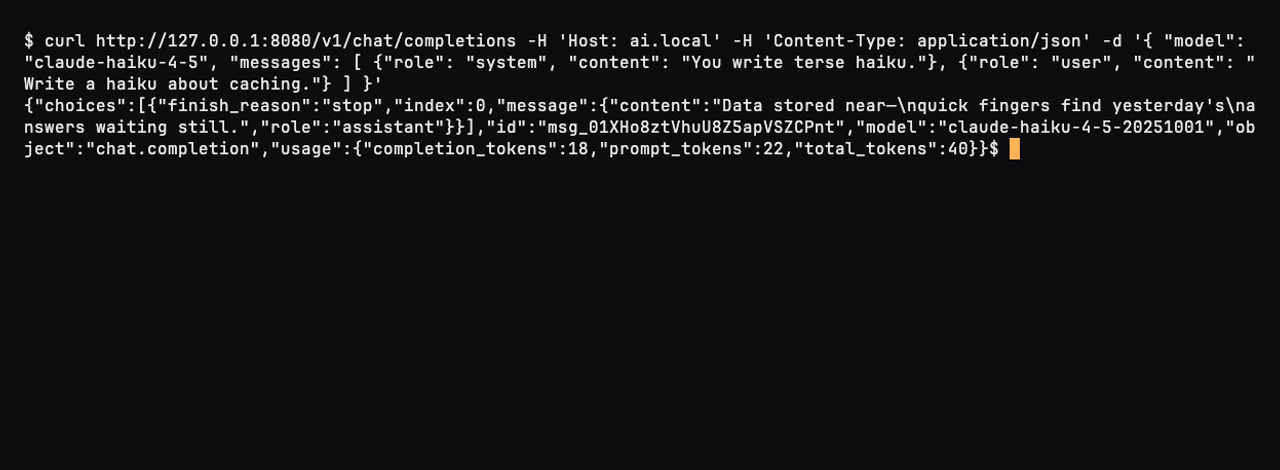
The recording shows the gateway's Anthropic format bridge against a hosted Claude upstream. A recording of this page's config, with the model running on a local GPU, lands with model-host GPU certification.
Your coding assistant streams your source code to somebody else's cloud, and the meter runs the whole session. Meanwhile the GPU in your workstation sits idle. SBproxy closes that gap with one Apache-2.0 binary that routes to 72 providers or serves the weights on your own hardware: "Take control of your AI traffic." This page sets up the serving half and points Claude Code, Cline, and Continue at it.
One honest note up front. The model host is landing in phases. The released binary ships GPU discovery and Hugging Face weight download, and the process launcher is tested against a fake engine, but real vLLM and llama.cpp bring-up is certified against actual GPUs in later phases of the work. sbproxy doctor reports what your host can do today; trust its verdict over any doc, this one included. See model-host.md in the repo docs for the current status.
What you will build
A gateway on port 8080 that hosts glm-4-flash on your GPU and answers to the name claude-sonnet-4-5. It speaks two wires at once: the Anthropic format on POST /v1/messages, which is what Claude Code sends, and the OpenAI format on POST /v1/chat/completions, which is what Cline and Continue send. Both resolve the same serve-entry alias, so one config serves every assistant on your team. A daily token budget watches the whole thing, because the governance planes treat a local model exactly like a hosted one.
Prerequisites
- A host with an NVIDIA GPU and driver.
sbproxy doctortells you whether the box qualifies and lists every blocker when it does not. - An inference engine on
PATH: a prebuiltllama-serverrelease, or vLLM viauv tool install vllmorpipx install vllm. SBproxy diagnoses missing engines and prints install steps; it never installs them for you. curlfor testing andjqfor readable output.- Claude Code, Cline, or Continue on the machine you code from.
Install
# Linux / macOS, single static binary:
curl -fsSL https://download.sbproxy.dev | sh

# macOS via Homebrew:
brew install soapbucket/tap/sbproxy

# Docker:
docker pull soapbucket/sbproxy:latest
The full install matrix, including packages and Kubernetes, is in the manual.
Minimal config
Save this as sb.yml. It ships as examples/use-case-coding-assistant, which also carries a compose file.
# yaml-language-server: $schema=./schemas/sb-config.schema.json
proxy:
  http_bind_port: 8080

origins:
  "localhost":
    action:
      type: ai_proxy
      providers:
        - name: local
          default_model: claude-sonnet-4-5
          models:
            - claude-sonnet-4-5
          serve:
            models:
              - model: glm-4-flash
                name: claude-sonnet-4-5
                keep_alive: 30m
The serve: block is the whole trick. glm-4-flash is a catalog id: the built-in catalog supplies the Hugging Face repo and quant variants, and the fit planner picks the quant your card can actually run. The gateway resolves the weights, spawns the engine as a supervised subprocess, and routes to it over loopback, which is why the provider carries no base_url. The name: field is the alias every plane sees. A request for claude-sonnet-4-5 lands on the local GLM, and since that is the model id Claude Code asks for by default, the client side shrinks to a base-URL change. keep_alive: 30m unloads the engine after thirty idle minutes so the VRAM comes back.
The origin key matters more than it looks. Hostname matching strips the port, so "localhost" matches a client whose base URL is http://localhost:8080. Running the gateway on a shared GPU box, key the origin with the hostname your clients will use instead.
Nothing here configures the Anthropic-format bridge, and that is the point. Every ai_proxy origin classifies POST /v1/messages as a native-format inbound surface and translates it to the same internal shape as chat completions, so both wires come free with the action type. See the supported-endpoints table in Providers.
Two optional blocks round it out, both in the shipped example:
      budget:
        on_exceed: log
        limits:
          - scope: workspace
            max_tokens: 2000000
            period: daily
Budgets, guardrails, and the usage ledger apply to the served model the same way they apply to a hosted one. on_exceed: log moves the gauge without blocking anyone; flip it to block when you mean it. The example also carries a commented-out anthropic provider that spills to the hosted API when the box is saturated, using routing: fallback_chain.
Run it
Check the config and the host before starting anything:
$ sbproxy validate sb.yml --format json
{"valid":true,"path":"sb.yml"}
$ sbproxy doctor
doctor prints the visible GPUs, which engines resolve on PATH, the weight-cache directory, and a final verdict on whether a serve: provider could admit a model on this host. Fix what it names before continuing. Then start the gateway:
sbproxy sb.ymlSend the first request on the wire Claude Code speaks. Expect it to be slow once: it pays for the weight download and the engine boot.
$ curl -s http://localhost:8080/v1/messages \
    -H 'Content-Type: application/json' \
    -d '{
      "model": "claude-sonnet-4-5",
      "max_tokens": 128,
      "messages": [{"role": "user", "content": "One sentence: where are you running?"}]
    }'
{
  "id": "msg_01...",
  "type": "message",
  "role": "assistant",
  "model": "claude-sonnet-4-5",
  "content": [{"type": "text", "text": "I am running on local hardware behind your gateway."}],
  "stop_reason": "end_turn",
  "usage": {"input_tokens": 19, "output_tokens": 12}
}
The response is Anthropic-shaped and the model field carries the alias, but a GLM on your GPU wrote the text. No API key changed hands; this config defines no virtual keys, so the gateway accepts the request as-is. Add virtual_keys from the Config Reference when you want per-client keys and quotas in front of the box.
Claude Code
First, the caveat, because it belongs before the command: Anthropic does not officially support non-Claude models behind Claude Code. What follows is a worked example of the Anthropic-format bridge, not a supported product configuration, and the tool's behavior against a third-party endpoint can change with any release. With that said, the client side is one variable:
export ANTHROPIC_BASE_URL=http://localhost:8080
claude
Claude Code asks for a Sonnet-class model id, the alias resolves it, and your prompts stop leaving the building. Two adjustments help in practice. If your Claude Code version defaults to a model name other than claude-sonnet-4-5, either change the name: in the serve entry to match or set ANTHROPIC_MODEL=claude-sonnet-4-5. Claude Code also uses a small model for background tasks; point that at the same alias with ANTHROPIC_SMALL_FAST_MODEL=claude-sonnet-4-5, since the config rejects model names outside its list.
Cline and Continue
Both speak the OpenAI wire, and the gateway serves it from the same config. In Cline, choose the OpenAI-compatible provider, set the base URL to http://localhost:8080/v1, and set the model id to claude-sonnet-4-5. The API key field can hold anything; nothing checks it until you add virtual keys. In Continue, add a model block to config.yaml:
models:
  - name: local-glm
    provider: openai
    model: claude-sonnet-4-5
    apiBase: http://localhost:8080/v1
Verify the wire the same way the editors will use it:
$ curl -s http://localhost:8080/v1/chat/completions \
    -H 'Content-Type: application/json' \
    -d '{"model":"claude-sonnet-4-5","messages":[{"role":"user","content":"Say hi."}]}' \
  | jq -r '.choices[0].message.content'
Hi! Ready when you are.
You are done when
curl -s http://localhost:8080/v1/messages with the request above returns HTTP 200, the body carries "model": "claude-sonnet-4-5" in Anthropic shape, and nvidia-smi on the gateway host shows the engine process holding VRAM while it answers. On a box without a GPU you can only get partway: sbproxy validate passes and the gateway logs a startup warning naming the model and the missing prerequisite, which is the designed behavior, not a bug.
Next steps
self-hosting.md- the self-hosting overview: manifests, cloud spill, and the OpenRouter parity mapmodel-host.md- theserve:reference: catalog, fit planner, supervisor, and the phased statusmodel-host-certification.md- provisioning a cloud GPU and certifying the real engine bring-up- AI Gateway - the routing, guardrail, budget, and ledger planes this config plugs into
- Config Reference - the full configuration schema, including virtual keys