This guide moves a LiteLLM proxy deployment to SBproxy in an afternoon. Your OpenAI-format clients keep working unchanged; you translate the config once and point traffic at the new port. What replaces the Python service is the "Take control of your AI traffic." binary: a single Apache-2.0 executable that routes to 72 providers, can serve the weights on your own GPUs, and works as a general reverse proxy at the same time, so the LLM gateway and the edge in front of it no longer have to be separate processes.
TL;DR
sbproxy config import-litellm litellm_config.yaml --out sb.yml
sbproxy sb.yml
import-litellm reads a LiteLLM config.yaml and writes an equivalent SBproxy sb.yml with one ai_proxy origin. It prints a warnings report to stderr listing every key that needs manual attention, and never fails on an unmapped key (only on a YAML parse error). Clients that already speak the OpenAI API need no change: keep calling /v1/chat/completions, /v1/embeddings, and the rest. os.environ/VAR references become SBproxy's ${VAR} interpolation.
What you will build
By the end you have an sb.yml that answers the same /v1/chat/completions calls your clients already make, keeping the public model names, per-model rate caps, and cache behavior your LiteLLM config declared. Anything the importer could not translate lands on a warnings list for you to handle by hand. The repo ships this walkthrough as a runnable pair in examples/migrate-litellm/: the LiteLLM config.yaml, the imported sb.yml annotated field by field, and a compose file that runs both proxies side by side so you can diff their answers before cutting over.
Why migrate
- SBproxy is a native-Rust proxy today. LiteLLM is mid-rewrite of its transformation core to Rust; you can skip the wait and run a Rust proxy now.
- One config covers both the AI gateway and a general reverse proxy, so the gateway, routing, auth, rate limiting, and WAF live in a single binary.
- The guardrail stack (injection, PII, jailbreak, toxicity, schema, context-poisoning, agent-alignment) is built in.
Prerequisites
- A LiteLLM
config.yaml. To rehearse on a safe copy first, use the one atexamples/migrate-litellm/config.yaml; the commands below run against it. OPENAI_API_KEYandANTHROPIC_API_KEYexported, since that example declares one model on each provider.curlfor sending requests andjqif you want readable JSON. You do not need a Rust toolchain or a Python environment.
Install
# Linux / macOS, single static binary:
curl -fsSL https://download.sbproxy.dev | sh

# macOS via Homebrew:
brew install soapbucket/tap/sbproxy

# Docker / Kubernetes:
docker pull soapbucket/sbproxy:latest
The runtime manual has the rest of the install matrix.
Automated migration
sbproxy config import-litellm <path> writes to stdout by default, or to a file with --out. The warnings report goes to stderr, so you can pipe a clean sb.yml while still seeing what needs review:
sbproxy config import-litellm litellm_config.yaml --out sb.yml
# warning: callback 'my_module.CustomHandler' looks like a Python hook ...
# config import-litellm: 1 key(s) need manual attention (see warnings above)
Validate the result before serving:
sbproxy validate sb.ymlField-by-field mapping
| LiteLLM | SBproxy |
|---|---|
model_list[].model_name | public model name (routable) and model_map key |
model_list[].litellm_params.model | upstream model; a provider/model prefix splits into provider_type + model |
litellm_params.api_key / api_base / api_version / organization | providers[].api_key / base_url / api_version / organization |
litellm_params.rpm / tpm | model_rate_limits[model].requests_per_minute / tokens_per_minute |
litellm_params.weight | providers[].weight |
Two model_list entries sharing a model_name | a model group: two providers listing that model, load-balanced by the routing strategy |
router_settings.routing_strategy | routing (simple-shuffle->round_robin, latency-based-routing->lowest_latency, usage-based-routing->least_token_usage, least-busy->least_connections, cost-based-routing->cost_optimized) |
litellm_settings.cache | semantic_cache.enabled |
os.environ/VAR (anywhere) | ${VAR} |
general_settings.master_key | proxy authentication (configure manually) |
general_settings.database_url | not needed: the runtime key/spend store is built in |
guardrails[] | a built-in or external guardrail adapter (review per entry) |
Worked example
LiteLLM config.yaml:
model_list:
  - model_name: gpt-4
    litellm_params:
      model: openai/gpt-4o
      api_key: os.environ/OPENAI_API_KEY
      rpm: 100
  - model_name: claude
    litellm_params:
      model: anthropic/claude-haiku-4-5
      api_key: os.environ/ANTHROPIC_API_KEY
router_settings:
  routing_strategy: latency-based-routing
litellm_settings:
  cache: true
Translated sb.yml:
proxy:
  http_bind_port: 8080
origins:
  ai.local:
    action:
      type: ai_proxy
      routing: lowest_latency
      providers:
        - name: openai
          provider_type: openai
          api_key: ${OPENAI_API_KEY}
          models: [gpt-4]
          default_model: gpt-4
          model_map: { gpt-4: gpt-4o }
        - name: anthropic
          provider_type: anthropic
          api_key: ${ANTHROPIC_API_KEY}
          models: [claude]
          default_model: claude
          model_map: { claude: claude-haiku-4-5 }
      model_rate_limits:
        gpt-4: { requests_per_minute: 100 }
      semantic_cache: { enabled: true }
The committed version of this pair at examples/migrate-litellm/ adds two more LiteLLM keys, a budget kwarg and a master_key, so you can watch the warning path fire on input the importer cannot translate.
Run it
Point the importer at the shipped example. It writes sb.yml and reports the two keys that need hands:
$ sbproxy config import-litellm examples/migrate-litellm/config.yaml --out sb.yml
config import-litellm: wrote sb.yml
warning: model 'claude': litellm_params.max_budget has no sbproxy mapping; review manually
warning: general_settings.master_key has no direct sbproxy mapping; configure proxy authentication (see the migration guide)
config import-litellm: 2 key(s) need manual attention (see warnings above)
Both warnings are expected here; the What needs manual migration section covers them. Validate, then serve:
$ sbproxy validate sb.yml
ok: sb.yml is a valid sbproxy config
$ export OPENAI_API_KEY=sk-...
$ export ANTHROPIC_API_KEY=sk-ant-...
$ sbproxy sb.yml
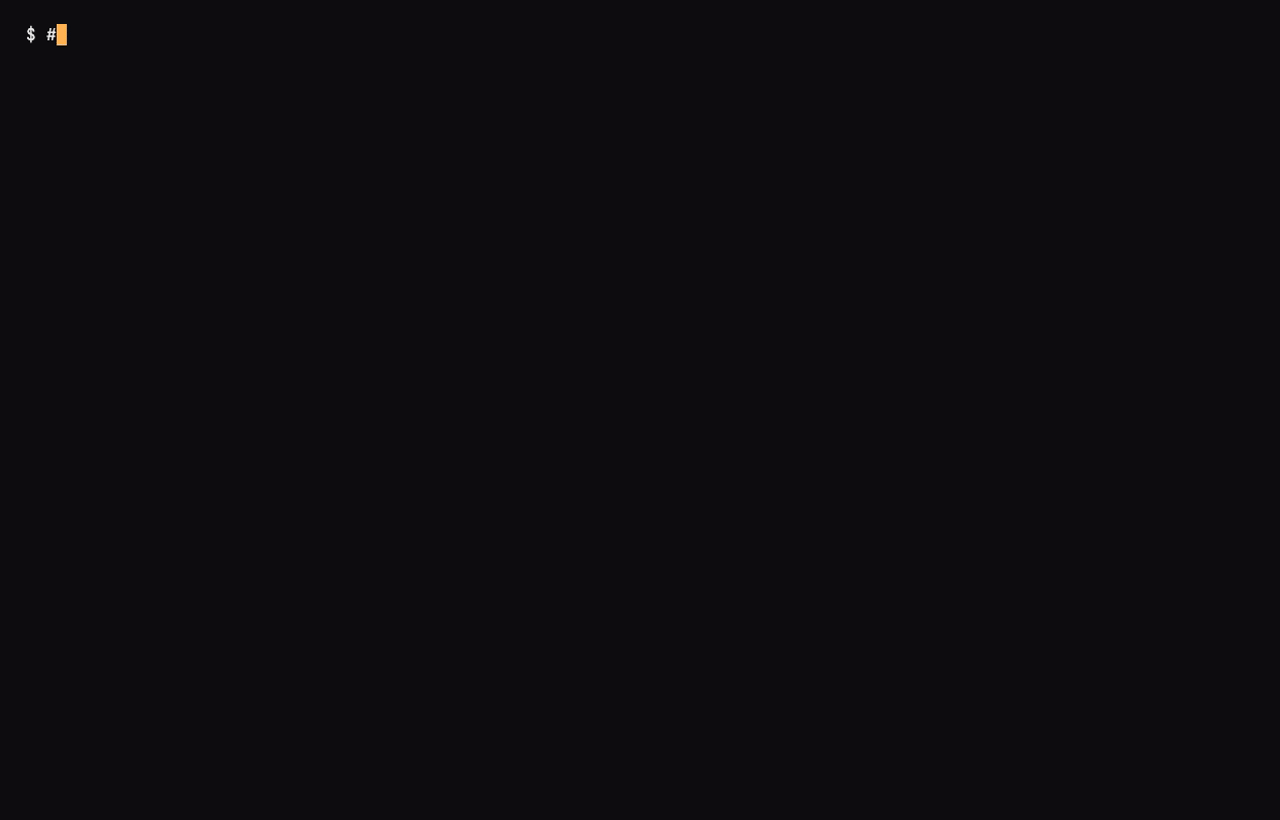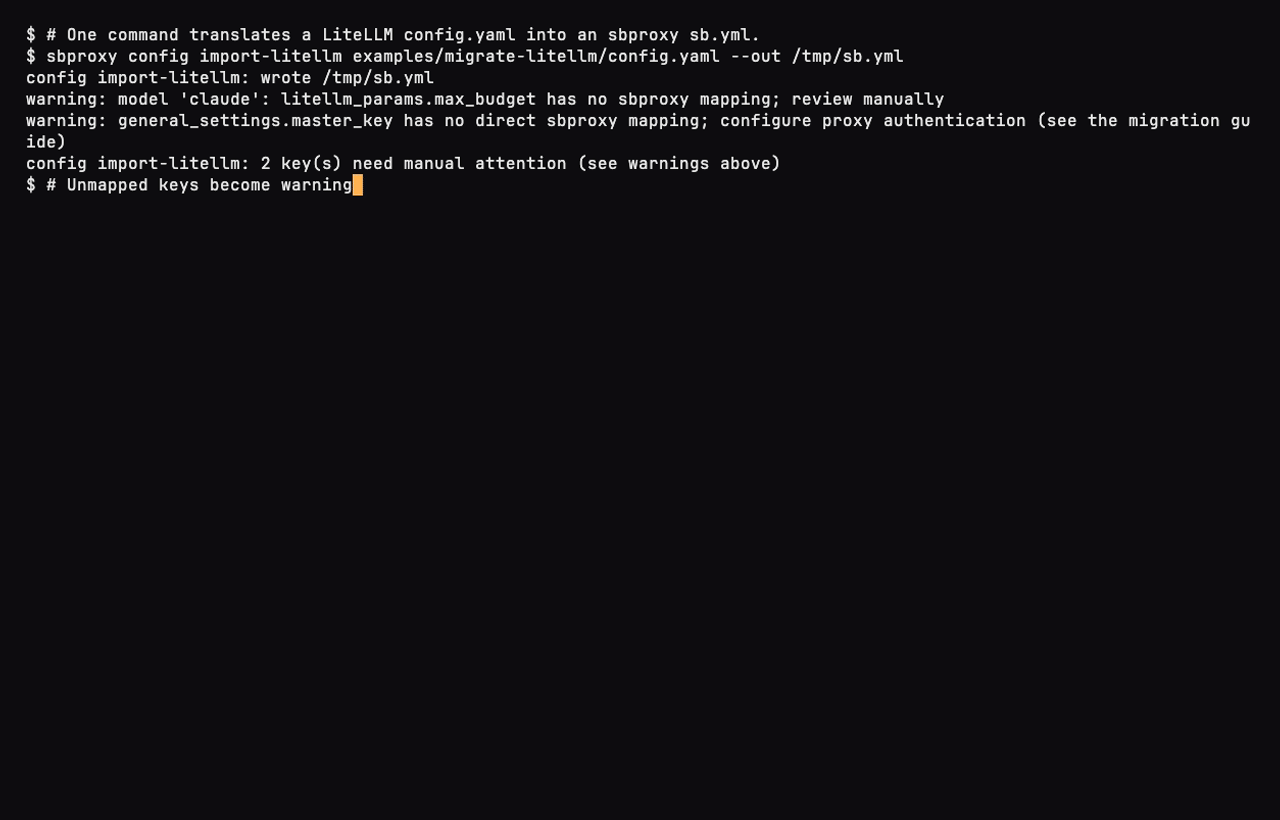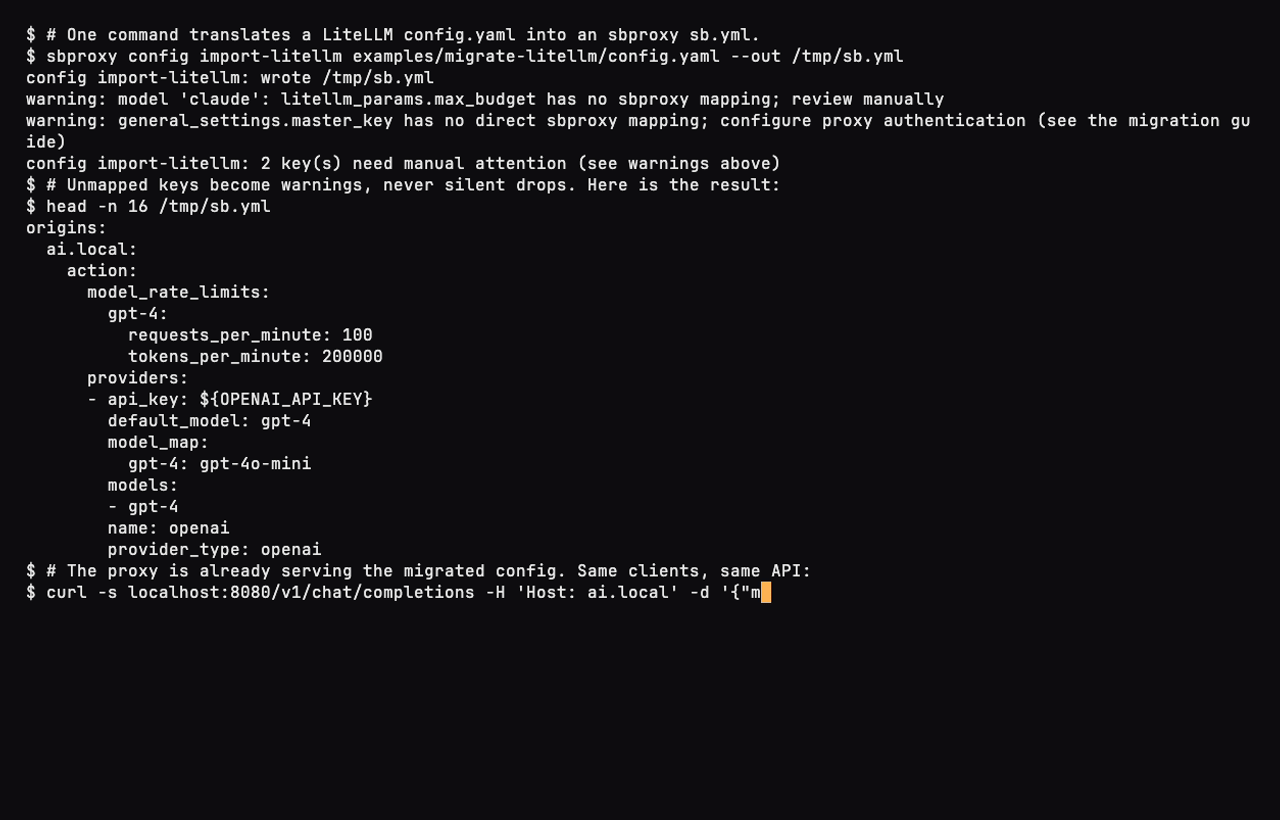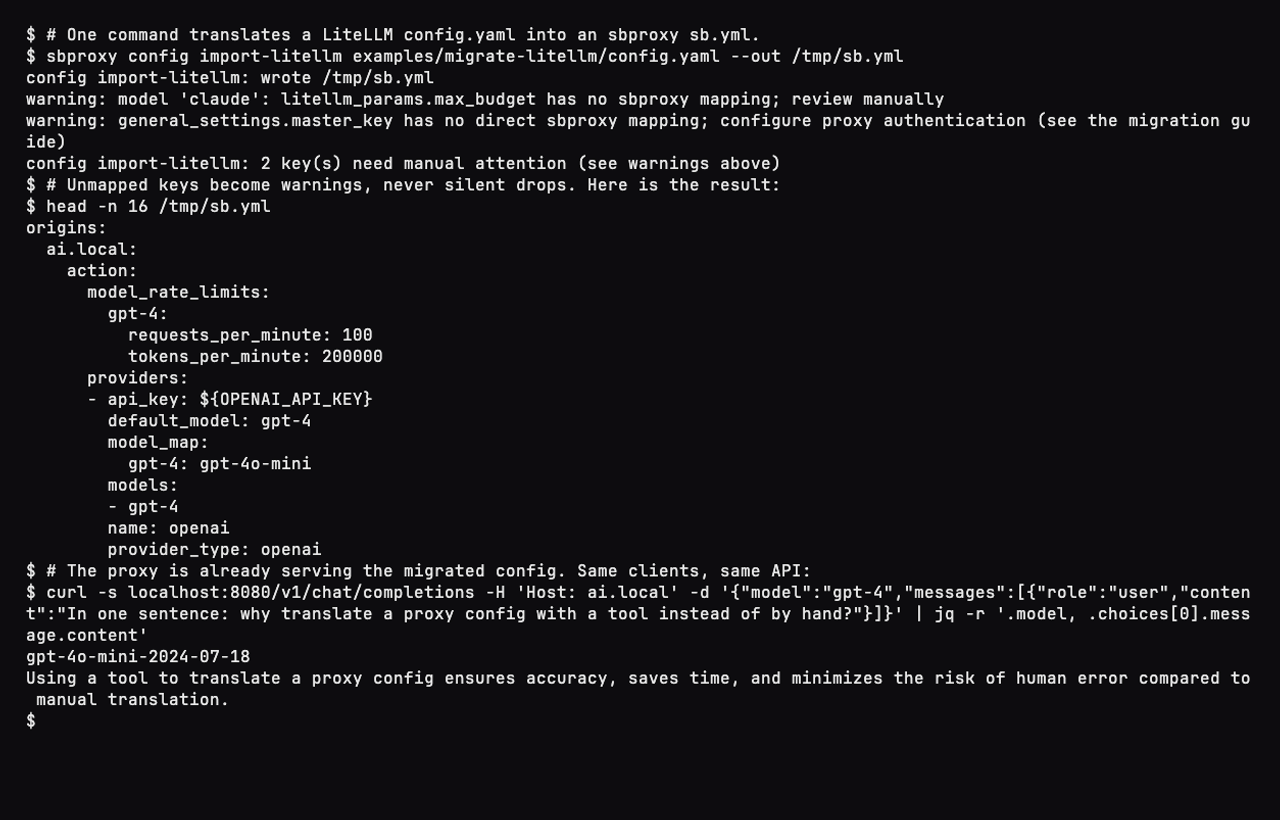
Send the request your clients already send, changing only the port:
$ curl -s http://127.0.0.1:8080/v1/chat/completions \
    -H 'Host: ai.local' \
    -H 'Content-Type: application/json' \
    -d '{"model": "gpt-4", "messages": [{"role": "user", "content": "Say hi."}]}'
{
  "id": "chatcmpl-...",
  "object": "chat.completion",
  "model": "gpt-4o-mini-2024-07-18",
  "choices": [{"message": {"role": "assistant", "content": "Hi! How can I assist you today?"}, "finish_reason": "stop"}],
  "usage": {"prompt_tokens": 10, "completion_tokens": 9, "total_tokens": 19}
}
The model field in the reply names the upstream model the public name mapped to through model_map. A request for "model": "claude" routes to Anthropic the same way.
To watch both proxies answer the same request before you retire LiteLLM, run docker compose up inside examples/migrate-litellm/. It starts LiteLLM from config.yaml on port 4000 and SBproxy from sb.yml on port 8080; the README there has the diff commands.
What needs manual migration
These have no automatic translation; the importer warns and points here.
- Python hooks given as module paths:
custom_auth,custom_sso,custom_key_generate, and callback classes. SBproxy's analog is CEL, Lua, JavaScript, or WebAssembly scripting; rewrite the logic in one of those. - Open-ended
litellm_paramskeyword arguments: the importer maps the known keys and warns on the rest, so review each warned key. Budget kwargs, for example, become an action-levelbudget:block (examples/ai-budget). - External guardrail providers (Presidio, Lakera, Aporia, Bedrock): map each to a built-in SBproxy guardrail or an external guardrail adapter.
general_settings.master_key: set up proxy authentication explicitly. Client keys move out of LiteLLM's database and into config, asvirtual_keysor acredentialsblock (examples/ai-virtual-keys).
What is deferred
Runtime parity for callback sinks, external guardrail adapters, multi-window budgets, per-error retry policy, and the /model/info family of endpoints is tracked separately and lands incrementally. The importer emits a warning for every unmapped litellm_params entry and wherever a mapped feature's target is not yet available. One known gap: unknown keys under litellm_settings, general_settings, and router_settings are ignored without a warning today, so diff the emitted sb.yml against your source config before you delete the original.
You are done when
sbproxy validate sb.ymlprintsok: sb.yml is a valid sbproxy config.- Every public model name from your
model_listreturns200through SBproxy withusage.total_tokensfilled in, from the same client code that called LiteLLM. - Each line of the importer's warnings report is either resolved (a
budget:block,virtual_keys, a rewritten hook) or deliberately parked.
Next steps
- examples/migrate-litellm/ - the runnable pair from this guide, plus the side-by-side compose file
- examples/ai-virtual-keys/ - per-team client keys, the follow-up for
master_key - examples/ai-budget/ - budget enforcement, the follow-up for budget kwargs
- AI Gateway - the AI gateway and routing strategies
- Config Reference - the full config schema, including
virtual_keysandbudget