Overview
SBproxy's AI Proxy supports fifteen routing strategies that determine how requests are distributed across LLM providers. Choose the strategy that best matches your requirements for latency, reliability, cost, or traffic distribution. All strategies work with retry configuration for automatic failover.
Available Strategies
- round_robin - Distribute evenly across providers in order. Default strategy.
- weighted - Route based on provider weight values. Higher weight means more traffic.
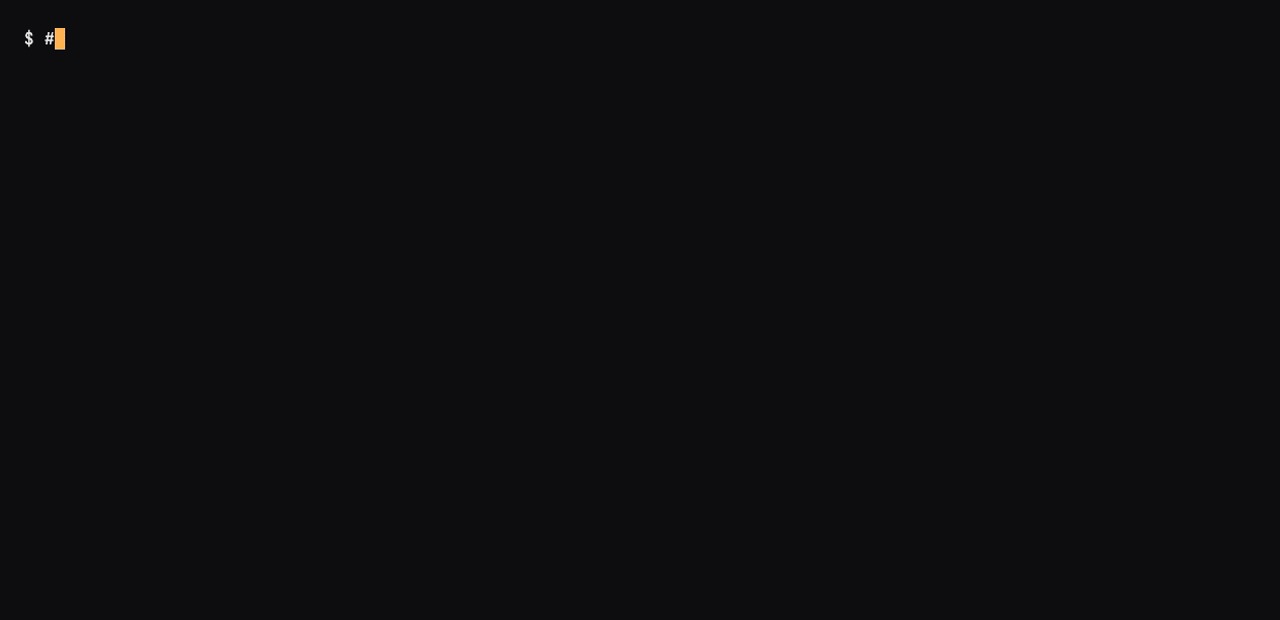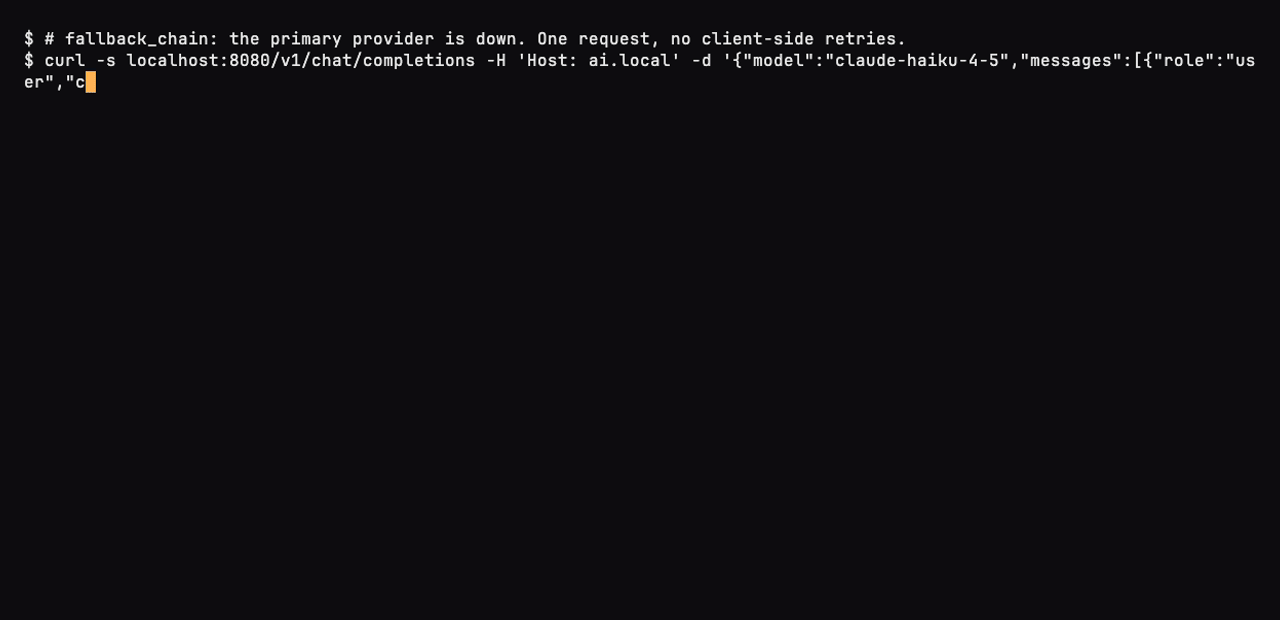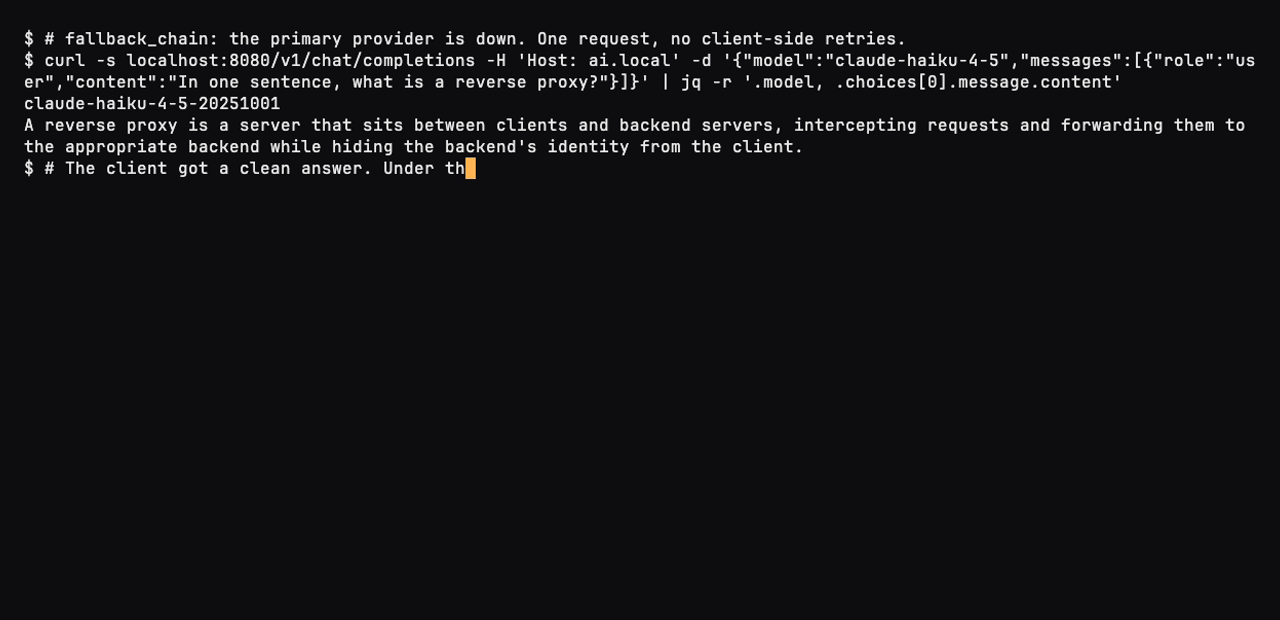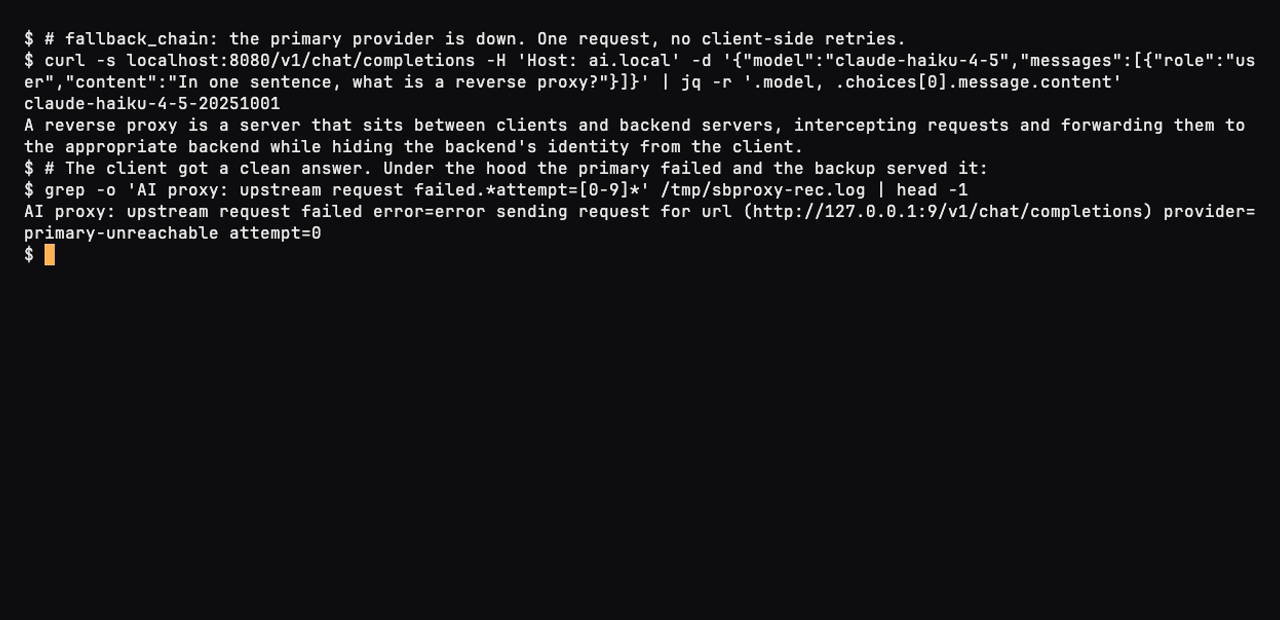
- fallback_chain - Try providers in specified order. Move to next on failure.
- cost_optimized - Route to the cheapest provider that can serve the request, based on the per-model pricing catalog.
- lowest_latency - Route to the provider with the lowest observed latency.
- least_connections - Route to the provider with the fewest active connections.
- sticky - Pin a user or session to the same provider. Falls back to round_robin for the initial pick.
- random - Pick a provider uniformly at random. Useful for spreading load when no other signal applies.
- token_rate - Route by per-provider token throughput, balancing tokens-per-minute headroom across the pool.
- least_token_usage - Route to the provider with the lowest absolute observed token throughput this minute. Suits self-hosted pools with no declared token cap.
- prefix_affinity - Hash a stable prefix of the request to a provider so shared-prefix requests reuse the same upstream's KV cache (vLLM, SGLang).
- peak_ewma - Power-of-two-choices over observed latency: sample two providers and pick the lower recent latency. Cuts tail latency under skew.
- race - Send the same request to multiple providers in parallel and take the first response. Optimizes latency at the cost of extra spend.
- cascade - Try (provider, model) tiers cheapest-first, grading each response against a quality threshold and escalating on a weak answer.
- cost_quality - Score each prompt's difficulty and send easy prompts to a cheap model, hard prompts to a frontier model, on a single dial.
Example
Weighted routing with automatic retry:
proxy:
  http_bind_port: 8080

origins:
  "ai.example.com":
    action:
      type: ai_proxy
      providers:
        - name: openai
          api_key: sk-...
          models: [gpt-4o, gpt-4o-mini]
          weight: 80
        - name: anthropic
          api_key: sk-ant-...
          models: [claude-sonnet-4-20250514]
          weight: 20
      routing:
        strategy: weighted
        retry:
          max_attempts: 3
          backoff_ms: 1000
          retry_on_status:
            - 429
            - 500
            - 502
            - 503
Test it:
curl -H "Host: ai.example.com" http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{"model": "gpt-4o-mini", "messages": [{"role": "user", "content": "Hello"}]}'