GPTBot, ClaudeBot, and PerplexityBot are in your access logs right now, pulling pages your team paid to produce. The usual response is a robots.txt entry or an outright block, which forfeits the one useful thing about this traffic: AI vendors will pay for licensed content when there is a machine-readable way to charge them. SBproxy's pitch is "Take control of your AI traffic.", and this guide is the govern half pointed at inbound traffic. The same Apache-2.0 binary that routes chat completions to 72 providers, or serves weights on your own GPUs, stands in front of your site, checks each crawler's cryptographic identity, quotes a price per fetch, and answers with HTTP 402 until a payment token arrives.
What you will build
One origin with two independent gates in front of it. The first gate is identity: the bot_auth provider verifies RFC 9421 HTTP Message Signatures (the IETF Web Bot Auth pattern) against a directory of agent public keys, and returns 401 to anything unsigned or signed with a key it does not know. The second gate is metering: the ai_crawl_control policy returns 402 Payment Required with a JSON challenge naming the price, and lets a request through when it carries a valid crawler-payment token. Each token redeems exactly once. A spoofed User-Agent gets past neither gate, because the User-Agent string is never what grants access; it only decides who gets charged.
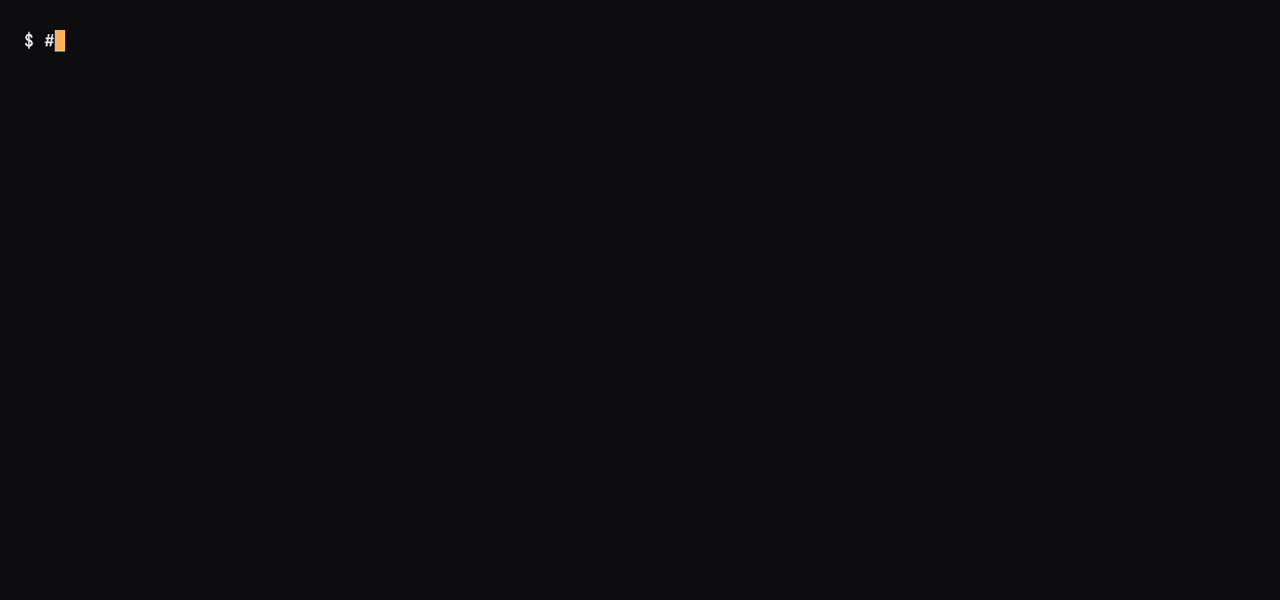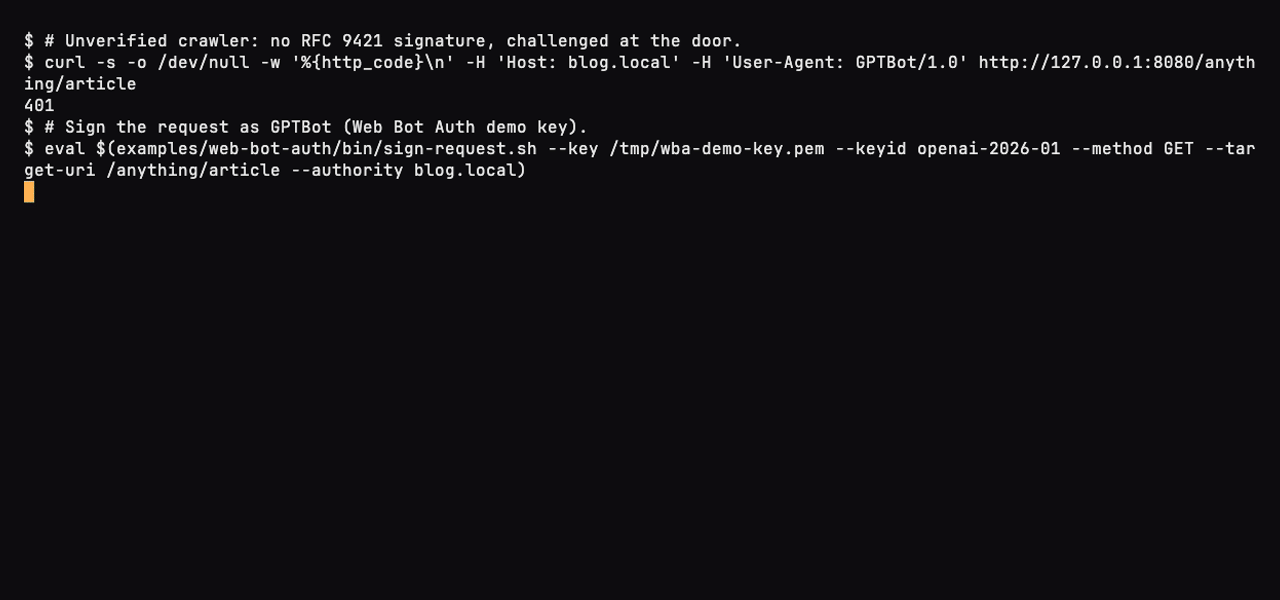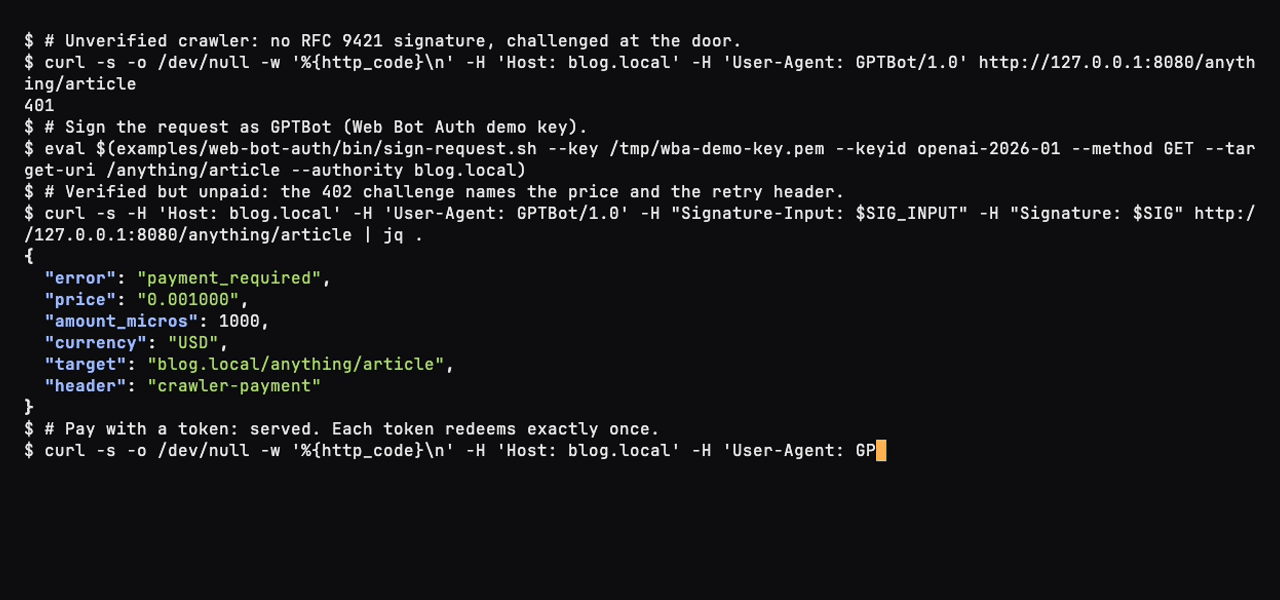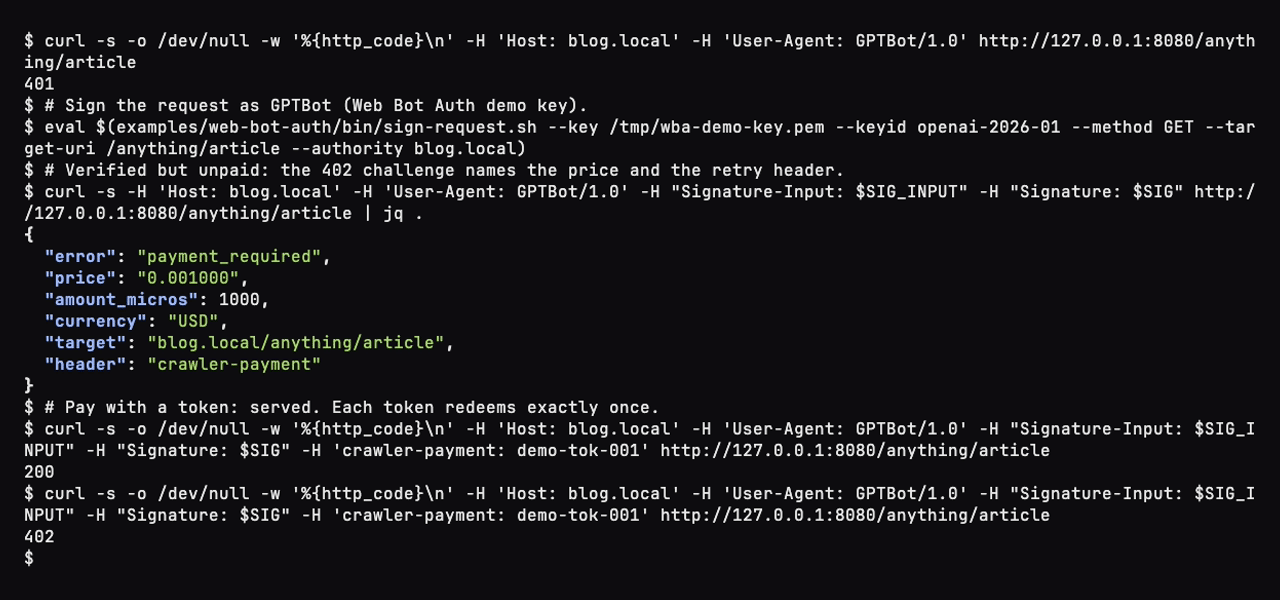
By the end you will have watched four requests on the wire: an unsigned crawler challenged with 401, a signed crawler without payment challenged with 402, the same crawler served with 200 after presenting a token, and the replayed token refused with a fresh 402.
One note on scope before you start: everything in this guide is Apache 2.0 code, including the 402 challenge bodies, the multi-rail negotiation and quote-token JWS described in 402-challenge.md, and the two ledgers that redeem tokens (in-memory for a single process, JSON-over-HTTPS for a fleet). In this walkthrough, "paying" means redeeming a token you seeded in the config; a production deployment issues tokens from its billing system through the HTTPS ledger client instead.
Prerequisites
- The
sbproxybinary (next section). curlfor sending requests andjqfor pretty-printing JSON.openssl, used by the bundled signing helper to produce Ed25519 signatures.- A checkout of the SBproxy repository, for the example config and the signing helper at
examples/web-bot-auth/bin/sign-request.sh. - No provider API keys. The demo upstream is the public echo service at
test.sbproxy.dev.
Install
# Linux / macOS, single static binary:
curl -fsSL https://download.sbproxy.dev | sh

# macOS via Homebrew:
brew install soapbucket/tap/sbproxy

# Docker:
docker pull soapbucket/sbproxy:latest
The full install matrix, packages, and checksums live in the manual.
Minimal config
The config below is examples/use-case-meter-crawlers/sb.yml. It proxies blog.local to the demo upstream and layers both gates on the origin.
proxy:
  http_bind_port: 8080

origins:
  "blog.local":
    action:
      type: proxy
      url: https://test.sbproxy.dev
Nothing unusual so far: one hostname, one upstream. Point url at your real origin when you take this to production.
    authentication:
      type: bot_auth
      clock_skew_seconds: 30
      agents:
        - name: openai-gptbot
          key_id: openai-2026-01
          algorithm: ed25519
          public_key: "d75a980182b10ab7d54bfed3c964073a0ee172f3daa62325af021a68f707511a"
          required_components:
            - "@method"
            - "@target-uri"
            - "@authority"
This is the identity gate. Crawlers that participate in Web Bot Auth sign every request with an Ed25519 key and advertise the key id in the Signature-Input header; the proxy verifies the signature against this directory and rejects everything else with 401. The required_components list forces each accepted signature to cover the verb, the path, and the host, so a captured signature cannot be replayed against a different route or origin. Two caveats worth knowing. The public_key above is the published RFC 8032 test vector, chosen so this walkthrough can sign requests without generating keys; in production you paste the vendor's real published key. And authentication applies to the whole origin, so every client on blog.local must sign, browsers included. Run this shape on a hostname you dedicate to agent traffic. On a mixed human-and-bot site, drop the authentication block and let the paywall below do the work alone; it never charges browser User-Agents.
    policies:
      - type: ai_crawl_control
        price: 0.001
        currency: USD
        header: crawler-payment
        crawler_user_agents:
          - GPTBot
          - ChatGPT-User
          - ClaudeBot
          - anthropic-ai
          - Google-Extended
          - PerplexityBot
          - CCBot
        valid_tokens:
          - demo-tok-001
          - demo-tok-002
          - demo-tok-003
This is the meter. A GET or HEAD from any User-Agent on the list, arriving without a redeemable token in the crawler-payment header, gets a 402 whose body names the price and the retry header. valid_tokens seeds the OSS in-memory ledger: three tokens, each spendable once, per process. That is deliberate for a demo and wrong for a fleet; multiple replicas need the HTTPS ledger client from Pay Per Crawl so one token spends across all nodes. Because bot_auth runs first, the ledger only ever hears from crawlers whose identity already checked out.
Run it
Start the proxy from the repository root:
sbproxy serve -f examples/use-case-meter-crawlers/sb.ymlFirst, the unverified crawler. No signature means the identity gate answers before the paywall is even consulted:
$ curl -si -H 'Host: blog.local' -H 'User-Agent: GPTBot/1.0' \
    http://127.0.0.1:8080/anything/article
HTTP/1.1 401 Unauthorized
content-type: application/json

{"error":"bot_auth: signature required"}
Now sign as GPTBot. Write the demo private key (a keypair RFC 8032 publishes as a test vector; its public half is already in the config) and let the bundled helper produce the two signature headers. Sign the components exactly as the proxy derives them: the path for @target-uri and the Host value for @authority:
printf -- '-----BEGIN PRIVATE KEY-----\nMC4CAQAwBQYDK2VwBCIEIJ1hsZ3v/VpguoRK9JLsLMREScVpezJpGXA7rAMcrn9g\n-----END PRIVATE KEY-----\n' \
  > /tmp/wba-demo-key.pem

eval $(examples/web-bot-auth/bin/sign-request.sh \
    --key /tmp/wba-demo-key.pem \
    --keyid openai-2026-01 \
    --method GET \
    --target-uri /anything/article \
    --authority blog.local)
The helper exports SIG_INPUT and SIG. The signed request passes the identity gate and lands on the meter, which quotes the price:
$ curl -si -H 'Host: blog.local' -H 'User-Agent: GPTBot/1.0' \
    -H "Signature-Input: $SIG_INPUT" -H "Signature: $SIG" \
    http://127.0.0.1:8080/anything/article
HTTP/1.1 402 Payment Required
content-type: application/json
crawler-payment: Crawler-Payment realm="ai-crawl" currency="USD" price="0.001000"

{"error":"payment_required","price":"0.001000","amount_micros":1000,"currency":"USD","target":"blog.local/anything/article","header":"crawler-payment"}
A cooperative crawler reads that body, pays out of band, and retries with the issued token. Here the token comes from the seeded list:
$ curl -s -o /dev/null -w '%{http_code}\n' \
    -H 'Host: blog.local' -H 'User-Agent: GPTBot/1.0' \
    -H "Signature-Input: $SIG_INPUT" -H "Signature: $SIG" \
    -H 'crawler-payment: demo-tok-001' \
    http://127.0.0.1:8080/anything/article
200
Run the exact same command again. The ledger already spent demo-tok-001, so the meter charges again:
$ curl -s -o /dev/null -w '%{http_code}\n' \
    -H 'Host: blog.local' -H 'User-Agent: GPTBot/1.0' \
    -H "Signature-Input: $SIG_INPUT" -H "Signature: $SIG" \
    -H 'crawler-payment: demo-tok-001' \
    http://127.0.0.1:8080/anything/article
402
Note that the replayed request reused the same signature headers and still passed the identity gate. The default signed components carry no per-request nonce, so that is expected; if your upstream needs one signature per request, add a caller-supplied nonce header such as x-replay-id to required_components, as Web Bot Auth describes.
You are done when
- The unsigned crawler request returns
HTTP/1.1 401 Unauthorizedwith"error":"bot_auth: signature required". - The signed, unpaid request returns
HTTP/1.1 402 Payment Requiredwith"error":"payment_required"and"price":"0.001000"in the body. - The signed request with
crawler-payment: demo-tok-001returns200once. - The identical request run a second time returns
402, proving the token was single-use.
Next steps
- Web Bot Auth covers the verifier in depth: verdicts,
content-digestbody binding, and publishing your own signing directory when SBproxy is the crawler. - Pay Per Crawl grows the flat price into tiers by route and content shape, per-vendor pricing through agent classes, and the HTTPS ledger with its retry and circuit-breaker rules.
402-challenge.mdis the wire contract: single-rail and multi-rail challenge bodies, quote tokens, the 406 fallback, and Cloudflare Pay Per Crawl interop viacloudflare_compat: true.rsl.mdand Content for agents advertise your terms so cooperative crawlers can discover them without a 402 round-trip:/licenses.xml,robots.txt,llms.txt, TDMRep, and Markdown or JSON projections of your pages.l402.mddocuments the Lightning-flavored macaroon credential surface if your buyers already speak L402.outbound-peer-pricing.mdis this story's mirror image: your own agents reading someone else's priced manifest and staying inside a budget.listings.mdpublishes a versioned, priced view of an origin once you have something worth selling.